正在加载视频...

视频加载失败

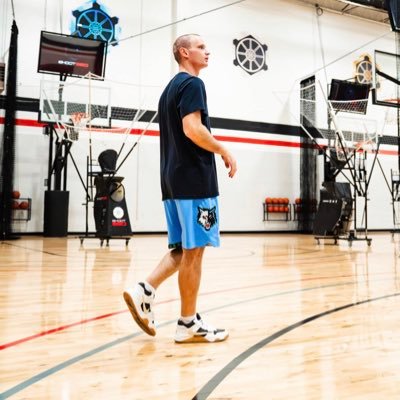
🚨 Do this drill to become an ELITE passer 🚨 Pound Dribble>Alternating BOUNCE/BEHIND THE BACK Passes🔥 - 20 reps each hand, 3 sets per hand - 5 free throws between each set Simple and effective work!💪 #basketball #basketballworkout
19,296 次观看 • 11 个月前 •via X (Twitter)

0 条评论

暂无评论

原始帖子的评论将显示在这里

相关视频

If you have lagging Arms and bringing them up to par is your TOP PRIORITY… I’d recommend doing something like this each week: Upper A • 2-3 sets of “The GREATEST Triceps exercise known to man” • 2-3 sets of Supinated Grip Curls w/ Upper Arm Support • 2-3 sets of Machine or Cable Overhead Extensions • 2-3 sets of Hammer Grip Curls w/ Upper Arm Support Upper B (Performed 3-4 days after Upper A) • 2-3 sets of Dip Machine • 2-3 sets of Machine or Cable Preacher Curls • 2-3 sets of “The GREATEST Triceps exercise known to man” OR Machine or Cable Overhead Extensions • 2-3 sets of Hammer Grip Curls w/ Upper Arm Support This will result in you doing somewhere between 8-12 sets of direct Bicep and Tricep work per week Low likelihood you need any more volume than that to improve your Arms mightily if following the notes below: 1) The ideal rep range to be using when performing the exercises mentioned is the 5ish to 10ish rep range — Choose a weight you can do for 5, 6, 7 reps @ 0-2 RIR…once you can do that weight for 8, 9, 10ish reps, increase the load by 5ish pounds 2) You should perform all reps of all the listed exercises with a controlled (but not overly slow) eccentric and an explosive (but still controlled) concentric 3) You should perform these exercises very early in your workout to ensure they are as efficient/effective as possible — If you perform them later on, you will not get as robust a growth stimulus from the sets because of the outstanding fatigue that will be present from the earlier sets/exercises in your workout Additional notes: - You may sub any of these exercises for comparable exercises due to preferences and/or equipment availability — Ex: Dip Machine subbed for Weighted Dips - I probably forgot something that I should’ve mentioned…if I think of it I’ll drop it in the post below

Dean Turner

66,141 次观看 • 5 个月前

Batch Normalization by hand ✍️ ~ 7 steps walkthrough below Batch normalization is common practice for improving training and achieving faster convergence. It sounds simple. But it is often misunderstood. 🤔 Does batch normalization involve trainable parameters, tunable hyper-parameters, or both? 🤔 Is batch normalization applied to inputs, features, weights, biases, or outputs? 🤔 How is batch normalization different from layer normalization? So I drew and calculated one entirely by hand. Goal: normalize a mini-batch of 4 examples to mean 0 and variance 1, then let the network scale it back. = 1. Given = A mini-batch of 4 training examples, each with 3 features. = 2. Linear layer = Let us multiply by the weights and add the biases. Batch norm sits after this, which answers the second question: what gets normalized is features, not inputs, weights or biases. = 3. ReLU = We apply the activation, and -2 becomes 0. Negative values are suppressed before any statistic is taken. = 4. Batch statistics = Let us compute the sum, mean, variance and standard deviation, one row at a time. A row is a feature and the four columns are the four examples, so every number here measures one feature against the rest of the batch. That is the "batch" in batch normalization, and it is exactly what layer normalization does not do. The statistics are rounded to whole numbers, which is what keeps the rest of the page doable in pen. = 5. Shift to mean 0 = We subtract the mean, in green. The four values in each feature now average to zero. = 6. Scale to variance 1 = Let us divide by the standard deviation, in orange. Each feature now has variance one, whatever scale it arrived at. = 7. Scale and shift = We multiply by a linear transformation and pass the result on. The diagonal and the last column are trainable, so having just forced every feature to mean 0 and variance 1, we hand the network the means to undo it. The outputs: Mean of each feature = [2, 1, 2] Std dev of each feature = [1, 1, 2] To the next layer = [2, -2, 2, 0], [-3, 3, 6, -3], [2, 0, 1, 2] The answers: 🤔 Both. The scale and shift are trainable, the statistics are not. Epsilon and the momentum on the running statistics are the hyper-parameters, and one mini-batch by hand needs neither. 🤔 Features, after the linear layer, not inputs, weights or biases. 🤔 Batch norm measures across the batch, one feature at a time. Layer norm measures across the features, one example at a time. 💾 Save this post!

Tom Yeh

20,848 次观看 • 2 个月前

Transformer by hand ✍️ ~ 6 steps walkthrough below Open the hood of a transformer and the parts list is overwhelming: embeddings, positional encoding, attention weighting, self-attention, cross-attention, multi-head attention, layer norm, skip connections, softmax, linear, Nx, shifted right, query, key, value, masking. Which of those actually make the car run? Two of them. Attention weighting and the feed-forward network. Everything else is an enhancement to make it run faster and longer, which is how we got from a car to a truck, and to the word "large" in large language model. So I drew and calculated those two parts entirely by hand. Goal: push five features through one transformer block, filling in every cell yourself. 1. Given Five positions of input features, arriving from the previous block. 2. Attention matrix Let us feed all five features to a query-key module (QK) and read back an attention weight matrix, A. The details of that module are a post of their own. 3. Attention weighting We multiply the input features by A to get the attention weighted features, Z. Still five positions. The effect is to combine features *across positions*, horizontally: X1 becomes X1 + X2, X2 becomes X2 + X3, and so on. 4. First layer Let us feed all five weighted features into the first layer of the FFN. Multiply by the weights and biases. This time the combining happens *across feature dimensions*, vertically, and each feature grows from 3 numbers to 4. Note that every position goes through the same weight matrix. That is what "position-wise" means. 5. ReLU We cross out the negatives. They become zeros. 6. Second layer Let us bring it back down: 4 dimensions to 3. The output feeds the next block, which has a completely separate set of parameters, and the whole thing runs again. You have just calculated a transformer block by hand. ✍️ The takeaway: the two parts are doing two different jobs, and neither one alone is enough. Attention mixes *across positions*, so a feature can see its neighbours. The FFN mixes *across feature dimensions*, so each position can think about itself. Horizontal, then vertical. Then that pattern repeats N times, each block with its own separate set of weights. That is the Nx from the list up top, and that is what makes the transformer run. 💾 Save this post! #AIbyHand #Transformers #DeepLearning

Tom Yeh

26,089 次观看 • 2 个月前

Ever heard the expression “shit rolls downhill”? Well we hit the bottom of the hill this week. Jobs were stacked way too tight on the schedule. Our operators were running 7 days a week, not finishing a job, and moving on to the next one with plans to return. Their hours were getting out of control too. Hitting 75 hours per week each. A surefire way to reach burnout. They’d be rushed to get to the next job, set a task to return to the last one, and move all the equipment over to the new one. This meant cash flow came to a screeching halt while expenses shot to the moon. Returning to a job to finish means a minimum of $500 in costs just to bring the equipment there and back. An unnecessary expense had we just took the time to finish properly in the first place. I’ve been nose deep in marketing and sales while this was happening and trusted that the production process was working. It wasn’t. They finally reached out and asked for help... at 8pm. We had 4 jobs set to start the next day and one of the trailers broke an axle. Rescheduling over 50 jobs is no easy task, and one they were all avoiding that created the problem in the first place. It’s difficult to tuck your tail between your legs and let a customer know their job needs to be pushed back up to 30 days. So I set into triage mode. Called each customer personally that was set to start the next day and let them know what was going on and what we needed to do. I then laid out every job on the schedule and set about not only fixing the current problem, but making sure it didn’t happen in the future. I wiped the jobs off the rest of the week so the team could go finish the jobs we left open ended and finish them properly. I then cleared every job off Fridays and weekends. This prevents burnout, overtime, and gives us 3 days a week to absorb rainouts, equipment issues, and job delays. This pushed the schedule 2 months further out, so I had to do the part everyone dreaded. Alerting the customers of their new start date. I reached out individually to each one to let them know. Fortunately, our customers are incredible and were very understanding. Nobody cancelled their job. Our operators have room to breathe, our quality can stay top notch, our cash flow returns, and the bandaid is ripped off. Now let’s get to work damnit!

Alex B

18,151 次观看 • 5 个月前