Video wird geladen...

Video konnte nicht geladen werden

Zur Startseite

Friday. 5:47 PM. Quick Claude session, small auth refactor. LGTM, merge, done. Monday, 10:00 AM. SSO is broken in production. Introducing Canary, the AI QA engineer that reads your codebase and catches broken user flows before production. Check it out at Congrats on the launch, Viswesh N G and team!
19,809 Aufrufe • vor 7 Monaten •via X (Twitter)

16 Kommentare

Profilbild von Afore Capital
Afore Capitalvor 7 Monaten

@RunCanary congrats @g_viswesh and team

Profilbild von conor brennan-burke
conor brennan-burkevor 7 Monaten

@RunCanary we love the product, super helpful to save time and effort on QA

Profilbild von jack mcclelland
jack mcclellandvor 7 Monaten

@RunCanary congrats on the launch

Profilbild von catherine jue
catherine juevor 7 Monaten

@RunCanary Congrats on the launch!!

Profilbild von sabir hussain
sabir hussainvor 7 Monaten

@RunCanary AI QA before prod saves serious headaches.

Profilbild von Cognixlab
Cognixlabvor 7 Monaten

@RunCanary Congrats on the launch, @g_viswesh and team!

Profilbild von Adarsh Kr Singh
Adarsh Kr Singhvor 7 Monaten

@RunCanary Huge congrats @g_viswesh & team! Finally an AI QA tool that actually groks the codebase instead of just poking at pixels. This could save so many Monday morning fires

Profilbild von Deals Dhamaka
Deals Dhamakavor 7 Monaten

@RunCanary SSO is the absolute worst place to trust an LLM with a quick auth refactor.

Profilbild von Hamza Ali
Hamza Alivor 7 Monaten

@RunCanary Congrats on the launch

Profilbild von Shamim Hossain
Shamim Hossainvor 7 Monaten

@RunCanary That’s great

Profilbild von Gregor
Gregorvor 7 Monaten

I've never had a Claude session catch auth refactors, but I'm curious, have you considered how @RunCanary would handle subtle changes to your existing codebase that aren't immediately apparent in a small refactor? What kind of edge cases would you use to test its effectiveness in this scenario?

Profilbild von ikan laut
ikan lautvor 7 Monaten

@RunCanary this is very interesting

Profilbild von Ramraj Velmurugan
Ramraj Velmuruganvor 7 Monaten

@RunCanary How do you make videos like this?

Profilbild von conor brennan-burke
conor brennan-burkevor 7 Monaten

@RunCanary let's goo

Profilbild von Clawdpad
Clawdpadvor 7 Monaten

The real question: can it catch the bugs that exist specifically because humans knew a fix was 'safe' based on intuition rather than verification? Most production outages trace back to confident assumptions, not uncertain ones. Does RunCanary model the confidence-error correlation?

Profilbild von Dog
Dogvor 7 Monaten

@RunCanary Someone gotta QA their website because the CTAs don’t fit

Ähnliche Videos

In the future, you’ll be able to accomplish a goal by just giving Claude an outcome and a budget. That’s the direction Anthropic is building in with its new Managed Agents features, announced at this week’s Code with Claude developer event. The basic idea: Claude, wrapped in a computer in the cloud, that you can spin up, scale, and manage as needed. Anthropic is taking on the infrastructure that kills most agent products, and making sure that it scales to meet the needs of agents running 24/7. On this week’s AI & I from Every 📧, I talk with Angela Jiang (Angela Jiang), head of product for the Claude platform, and Katelyn Lesse (Katelyn Lesse), head of engineering for the Claude platform, about what Anthropic is building and what it takes to make agents reliable in production. We get into: - Why the "build a generic harness, hot-swap any model behind it" playbook is already outdated. Angela points to eval data on Memory where the same task across different harnesses performed drastically differently. - The infrastructure wall every team hits in production—and why Katelyn thinks “my sandbox died and took the agent with it” is the real reason internal agents don't ship. - Why Anthropic is so bullish on using file systems and skills within Claude, including Angela's argument that those early design choices can compound for years. This is a must-watch for anyone trying to take an agent past the demo and into production. Watch below! Timestamps: How the Claude platform evolved from API to agents: 00:01:48 The primitives that make up Claude Managed Agents: 00:04:09 Why the harness and the model are becoming a single unit: 00:10:37 The infrastructure wall that kills most agent projects in production: 00:18:49 Why team agents need a different shape than individual productivity tools: 00:24:49 How Anthropic's legal team uses an agent to review marketing copy: 00:26:36 Using multi-agent orchestration for advisor strategies, adversarial pairs, and swarms: 00:34:24 How to measure agent success with outcome and budget as the end state: 00:35:50 What the platform looks like a year from now, when Claude writes its own harness: 00:39:11

Dan Shipper

66,871 Aufrufe • vor 5 Monaten

Claude Code + computer use is f*cking cracked 🤯 Build a landing page → Claude opens Chrome, looks at it, spots every issue, and fixes it — without you describing a single thing. All inside Claude Code. Perfect for DTC brands and agencies who are still vibe-coding landing pages and advertorials in Claude Code, then manually opening them in Chrome, spotting 15 things wrong, and describing every visual issue back to Claude one at a time. If you're building pages in Claude Code and your workflow looks like this — build the page, open it in Chrome, spot broken spacing, go back to Claude, type "the CTA button is too low and the hero image is cut off," wait for the fix, open Chrome again, find 3 new issues, describe those too ... Claude Code + computer use eliminates the entire loop: → Claude writes the full landing page or advertorial → Opens Chrome and navigates to it → Spots layout issues, broken spacing, off-brand colors, missing elements → Fixes everything and re-checks until the page looks right → Tests your Shopify product pages by clicking through like a real customer → Walks through your checkout flow and flags friction before customers hit it → You only see the finished, visually verified result No describing what you see on screen. No "the CTA button needs more contrast" back-and-forth. No being the eyeballs for an AI that can't see. What you get: → Landing pages and advertorials Claude builds AND visually QAs before you ever look at them → Product pages Claude clicks through — testing layout, images, and CTAs like a real user → HTML dashboards Claude opens and verifies the charts actually render → Checkout flows Claude walks through step by step to catch friction → All of it happening in one session — build, test, fix, done One prompt. Claude builds it, checks it, and fixes it. You just review the finished page. I put together a full playbook with the exact setup, the prompts, and 5 DTC workflows that use Claude Code + computer use. Want it for free? > Like this post > Comment "CLAUDE" And I'll send it over (must be following so I can DM)

Mike Futia

19,249 Aufrufe • vor 6 Monaten

The first campaign Viktor reviewed caught problems we didn't even know were there. We're a digital marketing team managing campaigns across multiple ad platforms, and before every launch someone on the team would manually check tracking, landing pages, targeting, budgets, creatives, and campaign settings. It was repetitive work, but missing just one detail could turn into wasted budget or inaccurate reporting. Instead of asking Viktor to help with individual checks, we gave him ownership of our entire campaign launch QA workflow. The first thing that stood out wasn't how quickly he worked. It was how thorough he was. Across one month, Viktor completed QA for 30 campaigns, executed 330 automated checks, and identified 47 issues, including 14 critical errors that could have affected campaign performance before a single campaign went live. By the time our team stepped in, all that was left was reviewing his findings and approving the launch. That completely changed the way we approached campaign launches. Instead of spending 65 hours every month on manual QA, our workflow was reduced to just 10.5 hours of strategic review giving our team back an estimated 54.5 hours to focus on optimization instead of repetitive checks. The biggest takeaway wasn't the time we saved. It was knowing every campaign went through the same level of quality control before launch. That's the difference we've started seeing between an AI assistant and an AI employee. An assistant waits for prompts. An AI employee owns recurring work while your team focuses on the decisions that matter most. Every campaign your team launches without this is a risk someone on your team is quietly absorbing. A copilot helps you work. An AI employee works when you don't. Hire Viktor for your team. $100 in credits included, no card. Full link in first comment. #AIemployee #MarketingOps #DigitalMarketing Paid Partnership

Kylie

92,501 Aufrufe • vor 2 Monaten

Claude Code tip: once Opus 5.5 is your main model, stop letting your Fable 5.1 quota go to waste put it on call with /advisor run /advisor fable Opus 5.5 keeps doing the work Fable 5.1 sits on the sidelines, reads the whole session, and steps in at three moments: → before a plan: is this right? → when the same error comes back: am I going the wrong way? → before "done": did I miss anything? Fable 5.1 advises. Opus 5.5 writes the code the same idea sits under Jev engineering: the expensive model stops weighing in on every step and only gets called at the moments that change the outcome • the full setup > Opus 5.5 on high runs the main session > subagent one reads code > subagent two edits and runs tests > subagent three looks up docs > all three on medium > Fable 5.1 on call hand the tree and this prompt to Claude Code 👇 "Set up my Claude Code to match this tree: 1. Reuse fitting subagents from ~/.claude/agents and .claude/agents. > Propose new ones only for missing roles > Set each to model: opus, effort: medium > Leave any that set a different model alone and list them 2. Set main session effort to high via effortLevel in ~/.claude/settings.json 3. Check for env vars that disable the advisor (CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY, anything that stops flag fetching) and CLAUDE_CODE_EFFORT_LEVEL, which overrides subagent effort. Report them, don't change them 4. Add a rule to ~/.claude/CLAUDE.md: ask the advisor before a big plan, when an error repeats, and before calling a long task done Show me the changes first. Don't edit files yet." ↳

Mr. Buzzoni

324,448 Aufrufe • vor 11 Tagen

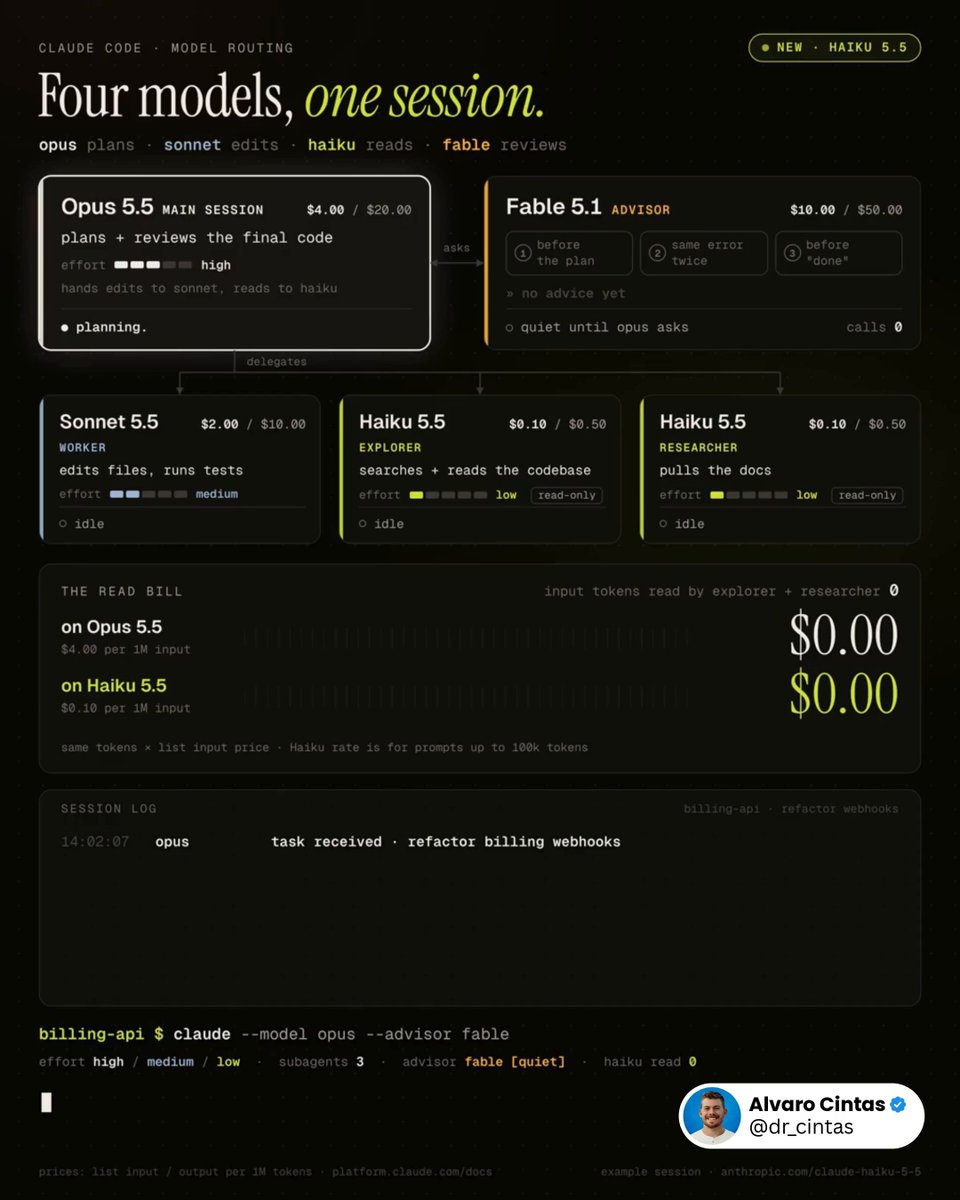
This workflow will save you thousands with Claude. Run Opus 5.5, Sonnet 5.5, Haiku 5.5, and Fable 5.1 together, and stop spending Opus tokens on work that doesn't need Opus. The entire idea in one line: Opus plans, Sonnet edits, Haiku reads, Fable reviews at decision points. Roles, broken down: - Opus 5.5, high effort, owns the plan and reviews the final code - Sonnet 5.5, medium effort, is the worker: edits files, runs tests - Haiku 5.5, low effort, splits into explorer (searches and reads the codebase) and researcher (pulls docs). it's the first Haiku with an effort setting - Fable 5.1, set with /advisor fable. Opus calls it at decision points, and it gets the full transcript each time Three moments Opus tends to call it: → before committing to a plan: is this the right approach? → the same error shows up again: is this going nowhere? → before marking the task done: did something get skipped? Why Haiku only reads: Anthropic's launch post says Sonnet 5.5 and Opus 5.5 are still the better choice for complex agentic coding (Terminal-Bench 4.0: 39.2% for Haiku 5.5, 70.6% for Sonnet 5.5) and that Haiku 5.5 fits narrowly scoped subagent work. so it gets the lookups, not the edits. Anyone still running one model for everything is paying $4 per million input tokens to check whether a file exists. Haiku 5.5 does it for $0.10. Drop this into Claude Code 👇 "Rebuild my Claude Code setup around this structure: Confirm Claude Code is v2.1.293 or later, so the haiku alias resolves to Haiku 5.5. If it isn't, stop and tell me to run claude update. Look through ~/.claude/agents and .claude/agents for subagents already covering explorer, worker, and researcher. Only create new ones for roles that are missing. Set model: haiku, effort: low on explorer and researcher, with no Edit or Write tools. Set model: sonnet, effort: medium on worker. If an existing subagent is locked to a different model, leave it as is and just list it. Name the explorer subagent Explore so it overrides the built-in one, which otherwise runs on my main model. In ~/.claude/settings.json, set advisorModel to fable, and set effortLevel to high for claude-opus-5-5 under modelSettings. A top-level effortLevel in user settings doesn't apply to Opus 5.5. Check for anything disabling the advisor: CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY, or anything blocking feature-flag fetches. Also check CLAUDE_CODE_EFFORT_LEVEL, which overrides subagent effort settings, and CLAUDE_CODE_SUBAGENT_MODEL_FORCE, which makes Claude Code ignore subagent model fields. Report what you find. Don't change any of it yet. Add one line to ~/.claude/CLAUDE.md: consult the advisor before a big plan, when the same error shows up twice, and before marking a long task done. Show every change as a diff first. Wait for my go-ahead before touching anything."

Alvaro Cintas

53,896 Aufrufe • vor 2 Tagen