正在加载视频...

视频加载失败

I don't understand why everyone isn't doing this yet. Anthropic's own Claude Code docs show how to run a whole team of Claudes, while Opus 5.5 only touches the plan and the merge the whole idea: agent teams in Claude Code one lead, separate teammates in their own context...

69,178 次观看 • 5 天前 •via X (Twitter)

4 条评论

Jadu 👐 的头像
Jadu 👐5 天前

the adversary staying review-only is the cleanest bit here lol

1Broom 的头像
1Broom5 天前

Giving the critic zero authorship is the smart call. A reviewer that didn't write a line has no ego tied up in the result, so it actually goes looking for the crack.

Martin Ronfort 的头像
Martin Ronfort5 天前

We actually went deeper on how agents can manage complex workflows like this here:

catman 的头像
catman5 天前

It’s like parallel work with a code reviewer at the gates: separate ownership speeds implementation, while adversarial checks catch contract and test failures before merge.

相关视频

Claude Code tip: stop burning Opus 5.5 context on tasks Sonnet 5.5 can swarm, while Fable 5.1 sits idle spin up an autonomous team with --agent claude --agent architect Opus 5.5 acts as the lead architect, scoping the work and validating every worktree before it merges Sonnet 5.5 teammates take isolated git worktrees and hammer out implementations at medium effort Fable 5.1 sits on the team as a dedicated adversary, only stepping in at three critical moments: → before a contract locks: does the frontend payload match the backend schema? → when a test breaks twice: are we patching the bug or just hiding the symptom? → before the merge: what attack surface or edge case did everyone overlook? Sonnet 5.5 builds. Fable 5.1 challenges. Opus 5.5 merges and ships Jev engineering runs the identical pattern one layer down: mechanical decisions that need no reasoning (which file to open, which tool to invoke, retry or abort) execute in 16ms, so the frontier models only wake up when execution paths actually diverge Plan on high. Delegate on medium. Keep the adversary on peer-to-peer call. - the full team setup > architect runs the main session on Opus 5.5 at high effort > teammate-ux builds client state inside its own git worktree > teammate-back writes endpoints and migrations inside a separate worktree > teammate-adv runs on Fable 5.1, read-only, and attacks every diff > teammates message each other by name without routing through the lead > tools: Agent(ux, backend, adversary) locks the architect to spawning only its own team paste the setup and this prompt into Claude Code below: "Configure my Claude Code workspace for an autonomous agent team: 1. Audit ~/.claude/agents and .claude/agents for definitions fitting architect, ux, backend and adversary > Generate definitions only for missing roles > Pin model: sonnet, effort: medium, isolation: worktree for ux and backend, and model: fable with read-only tools for adversary > Give architect model: opus, effort: high and tools: Agent(ux, backend, adversary) 2. Check ~/.claude/settings.json and my env: > Report CLAUDE_CODE_EXPERIMENTAL_AGENT_TEAMS if it's set, since it turns named subagents into teammates without worktrees > Report CLAUDE_CODE_SUBAGENT_MODEL_FORCE and CLAUDE_CODE_EFFORT_LEVEL, which can override the pinned models and effort 3. Write each role's prompt so ux and backend own separate folders, message each other by name when a contract changes, and hand every diff to adversary before reporting back 4. Add a team rule to ~/.claude/CLAUDE.md: no worktree merges until adversary has reviewed it Show every configuration diff first. Do not apply edits until confirmed" save it

Khairallah AL-Awady

32,018 次观看 • 3 天前

This is f*cking insane. This Claude Code tip saved me thousands of dollars. once Opus 5.5 is your main model, stop burning it on work Sonnet 5.5 can do, while Fable 5.1 sits idle hand the grunt work to Sonnet 5.5 subagents and put Fable 5.1 on call run /advisor fable Opus 5.5 plans and ships the final code Sonnet 5.5 subagents read, edit and run the tests Fable 5.1 reads the full session, every tool call included, and only speaks up at three points: → before a plan: is this the right approach? → when the same error comes back: am I digging in the wrong place? → before "done": what did I miss? Sonnet 5.5 builds. Fable 5.1 reviews. Opus 5.5 ships Jev engineering is the same move one layer down: the forks that need no thinker (which file, which tool, retry or stop) go to Jev in under half a second, and the big models only see the ones that split anyone still running one model for everything is paying Opus prices to decide whether a file exists - the full tree > Opus 5.5 on high runs the main session > explorer reads the code on Sonnet 5.5 > worker edits and runs tests on Sonnet 5.5 > researcher pulls the docs on Sonnet 5.5 > all three on medium > Fable 5.1 on call for main and every subagent paste the tree and this prompt into Claude Code ↓ "Rebuild my Claude Code setup around this tree: 1. Check ~/.claude/agents and .claude/agents for subagents that already fit explorer, worker and researcher. > Draft new ones only for missing roles > Give each model: sonnet, effort: medium > Skip any that pin a different model and list them 2. Set the main session to high via effortLevel in ~/.claude/settings.json, and set advisorModel to fable 3. Find anything that keeps the advisor off (CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY) plus CLAUDE_CODE_EFFORT_LEVEL, which overrides subagent effort. Report them, change nothing 4. Add one rule to ~/.claude/CLAUDE.md: consult the advisor before a large plan, when an error repeats, and before calling a long task done Show me every change as a diff first. No edits until I say go." ↳

delost

48,238 次观看 • 6 天前

Claude Code tip: once Opus 5.5 is your main model, stop leaving Fable 5.1 sitting idle and stop burning Opus tokens on tasks Sonnet 5.5 can swarm put it on call with /advisor run /advisor fable Opus 5.5 plans and ships the code Sonnet 5.5 swarms the routine work at medium effort Fable 5.1 reads the full session, every tool call included, and only speaks up at three points: → before a plan: is this the right approach? → when the same error comes back: am I digging in the wrong place? → before "done": what did I miss? Fable 5.1 reviews. Sonnet 5.5 executes. Opus 5.5 ships Jev engineering is the same move one layer down: the forks that need no thinker (which file, which tool, retry or stop) go to Jev in under half a second, and the big model only sees the ones that split Plan on high. Delegate on medium. Keep Fable on call. - the full tree > Opus 5.5 on high runs the main session > explorer reads the code > worker edits and runs tests > researcher pulls the docs > all three on Sonnet 5.5 at medium effort > Fable 5.1 on call as the advisor paste the tree and this prompt into Claude Code ↓ "Rebuild my Claude Code setup around this tree: 1. Check ~/.claude/agents and .claude/agents for subagents that already fit explorer, worker and researcher. > Draft new ones only for missing roles > Give each model: sonnet, effort: medium > Skip any that pin a different model and list them 2. Set the main session to high via effortLevel in ~/.claude/settings.json, and set advisorModel to fable 3. Find anything that keeps the advisor off (CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY, any variable that stops feature-flag fetching) plus CLAUDE_CODE_EFFORT_LEVEL, which overrides subagent effort. Report them, change nothing 4. Add one rule to ~/.claude/CLAUDE.md: consult the advisor before a large plan, when an error repeats, and before calling a long task done Show me every change as a diff first. No edits until I say go." ↳

mirku

421,711 次观看 • 11 天前

Claude Code tip, and it's absolute free f*cking gold: run Opus 5.5, Sonnet 5.5 and Fable 5.1 as one team and stop burning Opus tokens on routine work the setup in one line: plan on high, delegate on medium, keep Fable on call • who does what > Opus 5.5 on high - plans and ships the code > Sonnet 5.5 on medium - explorer reads code, worker edits and runs tests, researcher pulls docs > Fable 5.1 via /advisor fable - reads the whole session and speaks up only when it matters • when Fable 5.1 steps in -> before a plan: is this the right approach? -> when an error repeats: am I digging in the wrong place? -> before "done": what did I miss? Jev engineering takes it one layer lower: which file, which tool, retry or stop all go to Jev in under half a second, so the big models only see the real forks paste this into Claude Code ↓ "Rebuild my Claude Code setup: 1. Find subagents in ~/.claude/agents and .claude/agents that fit explorer, worker and researcher. Draft only the missing ones. Set each to model: sonnet, effort: medium. List any that pin a different model and leave them 2. In ~/.claude/settings.json set effortLevel to high and advisorModel to fable. 3. Report anything that disables the advisor (CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY, flag-fetching blockers) and CLAUDE_CODE_EFFORT_LEVEL. Change nothing. 4. Add to ~/.claude/CLAUDE.md: consult the advisor before a large plan, when an error repeats, and before calling a long task done. Show every change as a diff. No edits until I say go." ↳

Mr. Buzzoni

142,491 次观看 • 9 天前

Official Anthropic tip for Claude Code: stop burning Opus 5.5 context on tasks Sonnet 5.5 can swarm, while Fable 5.1 sits idle spin up an autonomous team with /teams claude --teammates ux,backend,adversary Opus 5.5 acts as the lead architect, scoping architecture and validating pull requests Sonnet 5.5 teammates take isolated git worktrees and hammer out implementations at medium effort Fable 5.1 monitors the peer-to-peer bus as a dedicated adversary, only stepping in at three critical moments: → before a contract locks: does the frontend payload match the backend schema? → when a test breaks twice: are we patching the bug or just hiding the symptom? → before calling done: what attack surface or edge case did everyone overlook? Sonnet 5.5 builds. Fable 5.1 challenges. Opus 5.5 merges and ships Jev engineering runs the identical pattern one layer down: mechanical decisions that need no reasoning (which file to open, which tool to invoke, retry or abort) execute in 16ms, so the frontier models only wake up when execution paths actually diverge Plan on high. Delegate on medium. Keep the adversary on peer-to-peer call. - the full team setup > Opus 5.5 on high coordinates the session and synthesizes PRs > teammate-ux builds client state inside a separate git worktree > teammate-back writes endpoints and handles Redis atomic locks > teammate-adv runs invariant fuzzing and catches replay vulnerabilities > all teammates communicate directly over peer-to-peer messaging without coordinator drag > tasks.json manages file-level mutex locks so nobody steps on another worktree paste the setup and this prompt into Claude Code below: "Configure my Claude Code workspace for autonomous agent teams: 1. Audit ~/.claude/teams and .claude/teams for teammate profiles fitting ux, backend, and adversary > Generate definitions only for missing roles > Pin model: sonnet, effort: medium for workers, and model: fable for adversary > Assign each worker an isolated git worktree branch to eliminate file conflicts 2. Enable agent teams in ~/.claude/settings.json: > Set CLAUDE_CODE_EXPERIMENTAL_AGENT_TEAMS=1 > Lock main session effortLevel to high 3. Initialize tasks.json in repo root with atomic file locking, allowing teammates to claim subtasks and resolve contracts directly over inter-agent messaging without coordinator intervention 4. Add a team rule to ~/.claude/CLAUDE.md: teammates must request an adversary security review before opening a pull request for the lead session Show every configuration diff first. Do not apply edits until confirmed" ↳

mirku

177,519 次观看 • 9 天前

Claude Code tip: once Opus 5.5 runs your main session, stop leaving Fable 5.1 on the bench put it on call with /advisor run /advisor fable Opus 5.5 keeps writing the code Fable 5.1 reads the whole session, every tool call included, and only speaks up at three moments: → before a plan: is this the right approach? → when the same error comes back: am I digging in the wrong place? → before "done": what did I miss? Fable 5.1 reviews. Opus 5.5 ships jev engineering is the same move one layer down: the forks that need no thinker (which file, which tool, retry or stop) go to jev in under half a second, and the big model only sees the ones that split - the full tree > Opus 5.5 on high runs the main session > explorer reads the code > worker edits and runs tests > researcher pulls the docs > all three on medium > Fable 5.1 on call as the advisor paste the tree and this prompt into Claude Code ↓ "Rebuild my Claude Code setup around this tree: 1. Check ~/.claude/agents and .claude/agents for subagents that already fit explorer, worker and researcher. > Draft new ones only for missing roles > Give each model: opus, effort: medium > Skip any that pin a different model and list them 2. Set the main session to high via effortLevel in ~/.claude/settings.json, and set advisorModel to fable 3. Find anything that keeps the advisor off (CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY, any variable that stops feature-flag fetching) plus CLAUDE_CODE_EFFORT_LEVEL, which overrides subagent effort. Report them, change nothing 4. Add one rule to ~/.claude/CLAUDE.md: consult the advisor before a large plan, when an error repeats, and before calling a long task done Show me every change as a diff first. No edits until I say go." ↳

Hanako

52,065 次观看 • 9 天前

Claude Code tip: once Opus 5.5 is your main model, stop leaving Fable 5.1 sitting idle put it on call with /advisor run /advisor fable Opus 5.5 keeps writing the code Fable 5.1 reads the full session, every tool call included, and only speaks up at three points: → before a plan: is this the right approach? → when the same error comes back: am I digging in the wrong place? → before "done": what did I miss? Fable 5.1 reviews. Opus 5.5 ships Jev engineering is the same move one layer down: the forks that need no thinker (which file, which tool, retry or stop) go to Jev in under half a second, and the big model only sees the ones that split - the full tree > Opus 5.5 on high runs the main session > explorer reads the code > worker edits and runs tests > researcher pulls the docs > all three on medium > Fable 5.1 on call as the advisor paste the tree and this prompt into Claude Code ↓ "Rebuild my Claude Code setup around this tree: 1. Check ~/.claude/agents and .claude/agents for subagents that already fit explorer, worker and researcher. > Draft new ones only for missing roles > Give each model: opus, effort: medium > Skip any that pin a different model and list them 2. Set the main session to high via effortLevel in ~/.claude/settings.json, and set advisorModel to fable 3. Find anything that keeps the advisor off (CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY, any variable that stops feature-flag fetching) plus CLAUDE_CODE_EFFORT_LEVEL, which overrides subagent effort. Report them, change nothing 4. Add one rule to ~/.claude/CLAUDE.md: consult the advisor before a large plan, when an error repeats, and before calling a long task done Show me every change as a diff first. No edits until I say go." ↳

delost

693,243 次观看 • 12 天前

this is pure f*cking treasure Claude Code tip: once Opus 5.5 is your main model, stop leaving Fable 5.1 sitting idle and stop burning Opus tokens on tasks Sonnet 5.5 can swarm put it on call with /goal claude --auto-mode "/goal all tests pass and lint is clean" Opus 5.5 keeps writing the code in auto mode Sonnet 5.5 swarms the routine work at medium Fable 5.1 inspects the full transcript and only speaks up at the turn boundary: → not yet met: am I drifting from acceptance criteria? → met: do the tests, diffs, and lint hold? → impossible: am I chasing an unreachable state? Fable grades. Opus ships JEV engineering is the same move one layer down: the forks that need no thinker (which file, which tool, retry or halt) go to JEV in under 16ms, and the big models only see the ones that split — the full tree > Opus 5.5 on high runs the main session > worker edits and patches code on Sonnet 5.5 > explorer indexes AST maps and call sites on Sonnet 5.5 > verifier runs tests and linters on Sonnet 5.5 > all three subagents on medium effort > Fable 5.1 on call as the Stop hook evaluator > JEV routes micro-forks under 16ms paste the tree and this prompt into Claude Code ↓ "Reconfigure my Claude Code setup around this tree: 1. Set the main session to Opus 5.5 on high effort with auto mode enabled. 2. Put Fable 5.1 on call as a session-scoped evaluator attached to the Stop hook: - Read-only transcript evaluation with zero tool calls - Three structured outcomes: not yet met (with steering notes), met (auto-clear), and impossible (abort early) 3. Spawn Sonnet 5.5 subagents on medium effort for worker, explorer, and verifier roles. Defer goal checks while background tasks run. 4. Route fast deterministic forks (tool resolution, path selection, auto-retries) through JEV. 5. Add one rule to CLAUDE.md: run long tasks with: claude --auto-mode \"/goal \" Show me every configuration change as a diff first. No edits until I say go." ↳

mirku

41,196 次观看 • 4 天前

This is f*cking insane. I spent thousands of dollars before I split my work across three models put Opus 5.5 on the plan, Sonnet 5.5 on the legwork and Fable 5.1 on call, and you stop spending Opus money on jobs it was never needed for who does what: Opus 5.5, high effort: makes the plan and owns the final diff Sonnet 5.5, medium effort, three jobs: explorer reads the code, worker edits files and runs tests, researcher pulls the docs Fable 5.1, through /advisor fable: reads the whole session, but only when it gets called Fable is consulted at three points: → before a plan ships: is this the right approach? → when an error comes back twice: is the search stuck in the wrong place? → before a long task counts as done: what got missed? Jev engineering applies the same split to the smallest decisions. which file to open, which tool to run, retry or stop need no reasoning, so Jev answers them in under half a second and the big models only get the real forks run Opus on everything and you pay it to check whether a file exists paste this into Claude Code: "Rebuild my Claude Code setup around three tiers. Look in ~/.claude/agents and .claude/agents for subagents that already cover explorer, worker and researcher. Create only the missing ones, each with model: sonnet and effort: medium. If an existing one is pinned to another model, list it and leave it alone. In ~/.claude/settings.json, set advisorModel to fable. Set high effort for Opus inside modelSettings for claude-opus-5-5, because a top-level effortLevel does not apply to Opus 5.5. Report, without changing anything: CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY or anything blocking feature-flag fetches, CLAUDE_CODE_EFFORT_LEVEL, which can override subagent effort, and whether Fable as advisor needs a one-time billing consent. If you can't tell, say so. Add one line to ~/.claude/CLAUDE.md: consult the advisor before a big plan, when the same error shows up twice, and before marking a long task done. Show every change as a diff first. Touch nothing until I say go."

Ryven

46,513 次观看 • 2 天前

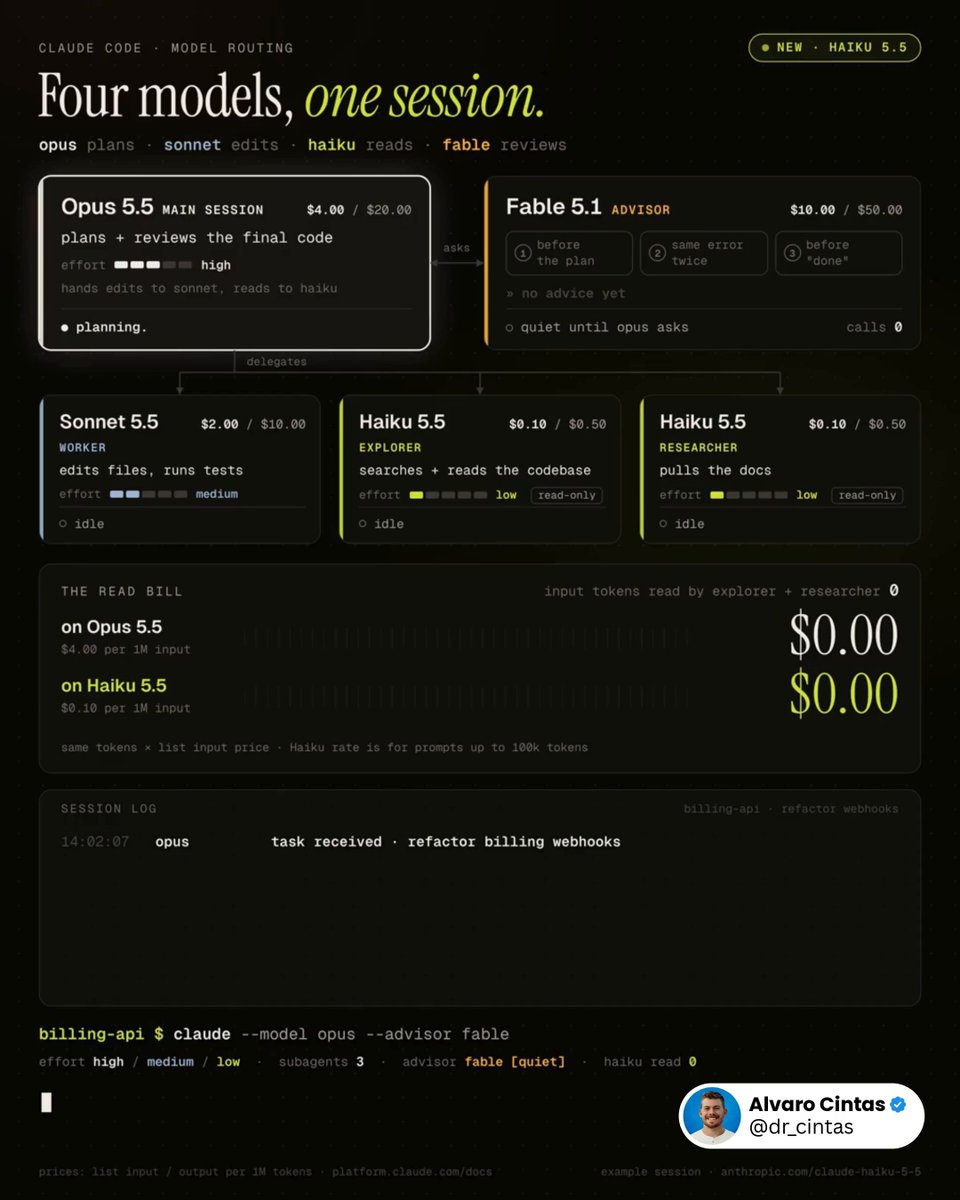
This workflow will save you thousands with Claude. Run Opus 5.5, Sonnet 5.5, Haiku 5.5, and Fable 5.1 together, and stop spending Opus tokens on work that doesn't need Opus. The entire idea in one line: Opus plans, Sonnet edits, Haiku reads, Fable reviews at decision points. Roles, broken down: - Opus 5.5, high effort, owns the plan and reviews the final code - Sonnet 5.5, medium effort, is the worker: edits files, runs tests - Haiku 5.5, low effort, splits into explorer (searches and reads the codebase) and researcher (pulls docs). it's the first Haiku with an effort setting - Fable 5.1, set with /advisor fable. Opus calls it at decision points, and it gets the full transcript each time Three moments Opus tends to call it: → before committing to a plan: is this the right approach? → the same error shows up again: is this going nowhere? → before marking the task done: did something get skipped? Why Haiku only reads: Anthropic's launch post says Sonnet 5.5 and Opus 5.5 are still the better choice for complex agentic coding (Terminal-Bench 4.0: 39.2% for Haiku 5.5, 70.6% for Sonnet 5.5) and that Haiku 5.5 fits narrowly scoped subagent work. so it gets the lookups, not the edits. Anyone still running one model for everything is paying $4 per million input tokens to check whether a file exists. Haiku 5.5 does it for $0.10. Drop this into Claude Code 👇 "Rebuild my Claude Code setup around this structure: Confirm Claude Code is v2.1.293 or later, so the haiku alias resolves to Haiku 5.5. If it isn't, stop and tell me to run claude update. Look through ~/.claude/agents and .claude/agents for subagents already covering explorer, worker, and researcher. Only create new ones for roles that are missing. Set model: haiku, effort: low on explorer and researcher, with no Edit or Write tools. Set model: sonnet, effort: medium on worker. If an existing subagent is locked to a different model, leave it as is and just list it. Name the explorer subagent Explore so it overrides the built-in one, which otherwise runs on my main model. In ~/.claude/settings.json, set advisorModel to fable, and set effortLevel to high for claude-opus-5-5 under modelSettings. A top-level effortLevel in user settings doesn't apply to Opus 5.5. Check for anything disabling the advisor: CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY, or anything blocking feature-flag fetches. Also check CLAUDE_CODE_EFFORT_LEVEL, which overrides subagent effort settings, and CLAUDE_CODE_SUBAGENT_MODEL_FORCE, which makes Claude Code ignore subagent model fields. Report what you find. Don't change any of it yet. Add one line to ~/.claude/CLAUDE.md: consult the advisor before a big plan, when the same error shows up twice, and before marking a long task done. Show every change as a diff first. Wait for my go-ahead before touching anything."

Alvaro Cintas

54,424 次观看 • 3 天前

this is straight f*cking gold for anyone on Claude Code you already pay for Fable 5.1, and while Opus 5.5 does all the work it just sits there one command puts it on your session as a senior reviewer: /advisor fable Opus 5.5 keeps writing the code Fable 5.1 reads the whole session, every tool call included, and speaks up at three moments only: > before a plan: is this the right approach? > when the same error comes back: am I digging in the wrong place? > before "done": what did I miss? Fable 5.1 reviews. Opus 5.5 ships Jev engineering does the same thing one layer down: forks that need no thinker (which file, which tool, retry or stop) go to Jev in under half a second, and the big model only sees the ones that actually split • the full tree > Opus 5.5 on high runs the main session > explorer reads the code > worker edits and runs tests > researcher pulls the docs > all three on medium > Fable 5.1 on call as the advisor paste the tree and this prompt into Claude Code ↓ "Rebuild my Claude Code setup around this tree: 1. Check ~/.claude/agents and .claude/agents for subagents that already fit explorer, worker and researcher. Draft new ones only for missing roles. Give each model: opus, effort: medium. Skip any that pin a different model and list them. 2. Set the main session to high via effortLevel in ~/.claude/settings.json, and set advisorModel to fable. 3. Find anything that keeps the advisor off (CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY, any variable that stops feature-flag fetching) plus CLAUDE_CODE_EFFORT_LEVEL, which overrides subagent effort. Report them, change nothing. 4. Add one rule to ~/.claude/CLAUDE.md: consult the advisor before a large plan, when an error repeats, and before calling a long task done. Show me every change as a diff first. No edits until I say go" ↳

Annatar.md

74,132 次观看 • 10 天前

Claude Code tip: once Opus 5.5 is your main model, stop letting your Fable 5.1 quota go to waste put it on call with /advisor run /advisor fable Opus 5.5 keeps doing the work Fable 5.1 sits on the sidelines, reads the whole session, and steps in at three moments: → before a plan: is this right? → when the same error comes back: am I going the wrong way? → before "done": did I miss anything? Fable 5.1 advises. Opus 5.5 writes the code the same idea sits under Jev engineering: the expensive model stops weighing in on every step and only gets called at the moments that change the outcome • the full setup > Opus 5.5 on high runs the main session > subagent one reads code > subagent two edits and runs tests > subagent three looks up docs > all three on medium > Fable 5.1 on call hand the tree and this prompt to Claude Code 👇 "Set up my Claude Code to match this tree: 1. Reuse fitting subagents from ~/.claude/agents and .claude/agents. > Propose new ones only for missing roles > Set each to model: opus, effort: medium > Leave any that set a different model alone and list them 2. Set main session effort to high via effortLevel in ~/.claude/settings.json 3. Check for env vars that disable the advisor (CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY, anything that stops flag fetching) and CLAUDE_CODE_EFFORT_LEVEL, which overrides subagent effort. Report them, don't change them 4. Add a rule to ~/.claude/CLAUDE.md: ask the advisor before a big plan, when an error repeats, and before calling a long task done Show me the changes first. Don't edit files yet." ↳

Mr. Buzzoni

324,943 次观看 • 12 天前

This is f*cking insane. This tip saved me thousands of dollars. run Opus 5.5, Sonnet 5.5, and Fable 5.1 together, and stop burning Opus on work it was never needed for. the whole idea in one line: the strong model plans, the mid-tier model executes, Fable stays quiet until it's actually needed. roles, broken down: Opus 5.5, high effort, owns the plan and ships the final code Sonnet 5.5, medium effort, splits into explorer (reads the codebase), worker (edits files, runs tests), researcher (pulls docs) Fable 5.1, called through /advisor fable, reads everything happening in the session but stays silent unless something's actually wrong three moments where Fable speaks: → a plan goes out: is this actually the right call? → the same failure shows up again: is the search going nowhere? → the task gets marked finished: did something get skipped? Jev engineering does the same thing one level down. the forks that don't need real thought, which file, which tool, keep going or stop, go straight to Jev and come back in under half a second. the big models only ever see the forks that genuinely need a decision. anyone still running one model for everything is paying Opus prices to decide whether a file exists. drop this into Claude Code: "Rebuild my Claude Code setup around this structure: Look through ~/.claude/agents and .claude/agents for subagents already covering explorer, worker, and researcher. Only create new ones for roles that are missing. Set model: sonnet, effort: medium on each. If an existing subagent is locked to a different model, leave it as is and just list it. In ~/.claude/settings.json, set effortLevel to high and advisorModel to fable. Check for anything disabling the advisor, CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY, or anything blocking feature-flag fetches, plus CLAUDE_CODE_EFFORT_LEVEL, which can override subagent effort settings. Report what you find. Don't change any of it yet. Add one line to ~/.claude/CLAUDE.md: check in with the advisor before a big plan, when the same error shows up twice, and before marking a long task done. Show every change as a diff first. Wait for my go-ahead before touching anything."

rvaniaaa

250,263 次观看 • 8 天前

holy f*ck. Official Anthropic tip for Claude Code: stop running agent teams on Opus and Sonnet 5.5 alone when Haiku 5.5 can swarm the bus at 340 tok/s spin up an autonomous team with /teams claude --teammate-mode auto Opus 5.5 acts as the lead architect, scoping architecture and validating pull requests Sonnet 5.5 teammates take isolated git worktrees and hammer out implementations at medium effort Haiku 5.5 swarms the peer-to-peer bus as a dedicated scout and fuzzer, only stepping in at three critical moments: → before a contract locks: does the frontend payload match the backend schema? → when a test breaks twice: are we patching the bug or just hiding the symptom? → before calling done: what attack surface or edge race did everyone overlook? Sonnet 5.5 builds. Haiku 5.5 swarms. Opus 5.5 merges and ships Jev engineering runs the identical pattern one layer down: mechanical decisions that need no reasoning (which file to open, which tool to invoke, retry or abort) execute in 16ms, so the frontier models only wake up when execution paths actually diverge Plan on high. Delegate on medium. Keep Haiku 5.5 on P2P call. - the full team setup > Opus 5.5 on high coordinates the session and synthesizes PRs > teammate-ux builds client state inside a separate git worktree > teammate-back writes endpoints and handles Redis atomic locks > teammate-scout runs invariant fuzzing and AST parsing on Haiku 5.5 at 340 tok/s > all teammates communicate directly over peer-to-peer messaging without coordinator drag > tasks.json manages file-level mutex locks so nobody steps on another worktree paste the setup and this prompt into Claude Code below: "Configure my Claude Code workspace for autonomous agent teams: 1. Enable experimental agent teams in ~/.claude/settings.json: > Set CLAUDE_CODE_EXPERIMENTAL_AGENT_TEAMS to 1 in env block > Set teammateMode to auto > Pin main lead model: opus with effortLevel: high 2. Audit ~/.claude/agents and create teammate profiles fitting ux, backend, and scout: > teammate-ux: model: sonnet, effort: medium, isolation: worktree > teammate-back: model: sonnet, effort: medium, isolation: worktree > teammate-scout: model: haiku, tools: Read, Grep, Glob, SendMessage 3. Configure shared task coordination in ~/.claude/CLAUDE.md: > Initialize tasks.json for task dependencies and atomic file mutexes > Teammates resolve contracts directly over peer-to-peer messaging without lead intervention > Enforce Haiku scout schema verification before teammates mark tasks completed 4. Quality gate: > Opus lead reviews synthesized worktree diffs and validates test suites before final merge Show every configuration diff first. Do not apply edits until confirmed" ↳

mirku

82,064 次观看 • 2 天前

holy sh*t. Official Anthropic tip for Claude Code: stop burning Opus 5.5 context on tasks Haiku 5.5 can swarm, while Sonnet 5.5 builds put the architect on call with /advisor claude --advisor opus --subagents haiku Sonnet 5.5 drives the primary session on high effort, writing diffs and running test suites Haiku 5.5 subagents swarm the repo in parallel at 340 tok/s, handling file discovery and spec docs lookup Opus 5.5 stays on call in the background as the advisor, only stepping in at three critical moments: → before a plan locks: does the implementation plan miss auth invariants or schema contracts? → when a test breaks twice: are we fixing the root cause or falling into a recursive rabbit hole? → before calling done: did the full diff introduce hidden regressions or break pre-flight rules? Opus 5.5 reviews. Sonnet 5.5 builds. Haiku 5.5 swarms Jev engineering runs the identical pattern one layer down: mechanical decisions that need no reasoning (which file to open, which tool to invoke, retry or abort) execute in 16ms, so the frontier models only wake up when execution paths actually diverge Plan on high. Delegate on medium. Keep Opus on call. - the full advisor setup > Opus 5.5 on call reads full session history and catches deep architectural traps > Sonnet 5.5 lead drives edits, writes core logic, and executes test harnesses > Haiku 5.5 subagents swarm AST parsing, grep scans, and API docs in parallel > JEV micro-fork layer resolves 1,500+ mechanical routing branches in under 16ms > advisor stays completely silent on routine bash execution to protect context paste the setup and this prompt into Claude Code below: "Configure my Claude Code workspace for hierarchical advisor orchestration: 1. Audit ~/.claude/settings.json and project config for model roles fitting lead, subagents, and advisor: > Pin main session model: sonnet with effortLevel: high for primary execution > Pin subagents model: haiku with effortLevel: medium for parallel file discovery and docs retrieval > Pin advisor model: opus on call for strategic review 2. Enable the advisor tool in ~/.claude/settings.json: > Set advisorModel to claude-opus-5-5 > Enable subagent parallel dispatcher pool (3x workers) 3. Configure automatic advisor consultation checkpoints in ~/.claude/CLAUDE.md: > Consult /advisor opus before finalizing multi-file architecture plans > Automatically summon /advisor opus when the same test or compiler error fails twice > Enforce advisor diff contract audit before declaring tasks complete or staging git commits 4. Constrain subagent scopes: > Haiku subagents return structured AST summaries and docs snippets only without modifying main session context Show every configuration diff first. Do not apply edits until confirmed" ↳

mirku

725,531 次观看 • 3 天前

Official Anthropic tip for Claude Code: don't exhaust Opus 5.5 context on repetitive multi-file routines when Sonnet 5.5 can swarm them in parallel and Fable 5.1 can verify the result turn mass-agent sweeps into deterministic code with dynamic workflows claude --effort ultracode /workflows Opus 5.5 acts as the lead architect, drafting the workflow script, setting input schemas, and synthesizing final verified reports Sonnet 5.5 workers swarm the execution pipeline across dozens of files, handling bulk refactors and migrations at medium effort Fable 5.1 stands by as the dedicated verifier, entering the pipeline at three decisive moments: → before a fan-out: does this workload justify a 50-agent script or can a tight 5-step pipeline solve it? → on worker failure: can the step replay from cache or does the pipeline branch need a clean rerun? → before reporting: did every reported finding survive adversarial cross-checking and voting? Sonnet 5.5 executes. Fable 5.1 cross-examines. Opus 5.5 authors and reports Jev engineering runs the identical pattern one layer down: mechanical choices that need no cognitive reasoning (which file to inspect, which tool to invoke, retry or stop) resolve in 16ms, so frontier models only wake up when execution paths actually split Plan on high. Delegate on medium. Keep Fable on call. - the full workflow architecture > Opus 5.5 on high drafts the orchestration script inside .claude/workflows/ > pipeline() fans out Sonnet 5.5 workers across target paths concurrently > each worker operates inside an isolated working copy to eliminate file collisions > Fable 5.1 cross-checks claims and votes down unverified findings > intermediate state lives in script variables, leaving Claude's context 100% clean > 1h prompt cache prefix hold eliminates redundant system prompt processing paste the setup and this prompt into Claude Code below: "Configure my Claude Code workspace for dynamic workflows: 1. Audit ~/.claude/workflows and .claude/workflows for existing scripts: > Draft workflow definitions for codebase audits, parallel migrations, and adversarial verification > Pin model: sonnet, effort: medium for pipeline workers, and model: fable for verifier agents > Configure workers to operate on isolated copies to eliminate edit conflicts 2. In ~/.claude/settings.json, enable dynamic workflows: > Set ultracode = true > Lock main session effortLevel to high > Set subagentPromptCacheTtl = '1h' to share prompt prefixes across parallel fan-outs 3. Set workflow runtime controls: > Set autoContinueAtUsageLimit = true so long batch runs automatically resume after limit resets > Set CLAUDE_CODE_WORKFLOW_PREFIX_STAGGER_MS = 5000 for prompt prefix caching > Set large workflow warning threshold to 25 agents 4. Add a rule to ~/.claude/CLAUDE.md: all multi-file audits must pass an adversarial Fable cross-check before findings are reported to the lead session Show every configuration diff first. Do not apply edits until confirmed" ↳

mirku

18,295 次观看 • 7 天前