Loading video...
Video Failed to Load
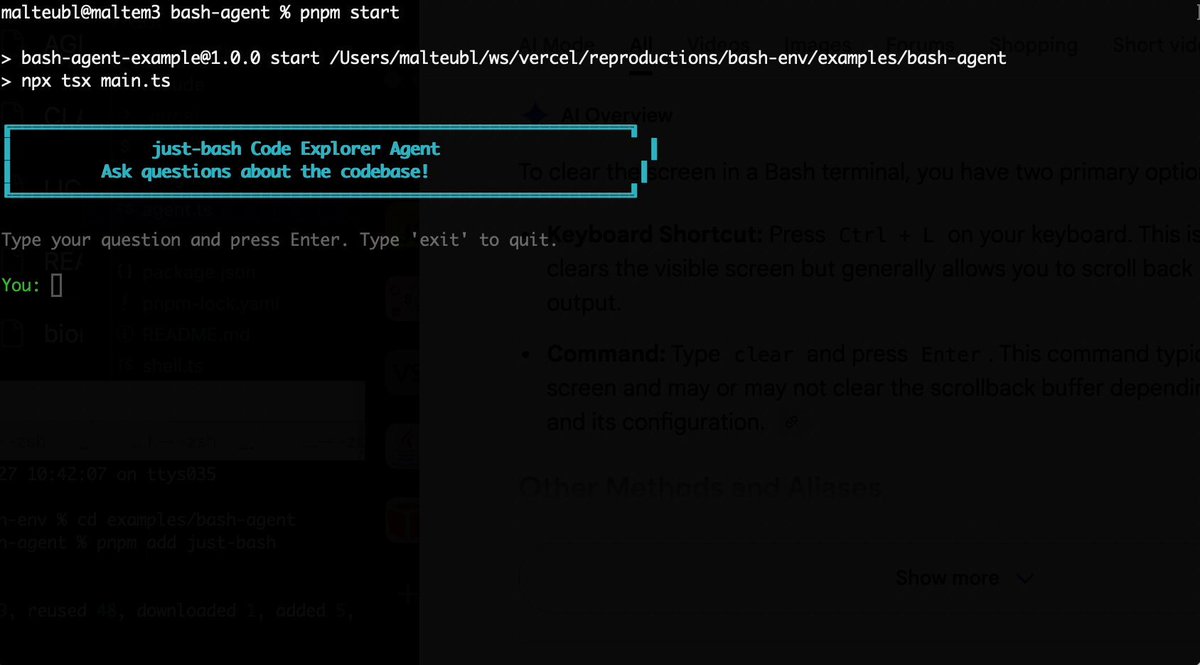
i just put Jev inside an open agent harness. (150x cheaper decision-making than LLM) agents burn a lot of tokens on decisions that are really just picking one option from a short list, like matching a client request to the right GitHub issue. so i built a weekly client... show more
16,871 views • 1 month ago •via X (Twitter)
36 Comments

Routing the pick from a short list decisions away from the big model is the right instinct. The confidence score is the part I care about more than the 150x. 5 bad matches caught out of 40 is a lot, so I would want to see how that holds on 400.

The 40-request test is too small to establish how reliably confidence routes errors to review. Review caught 5 wrong matches, but one confident wrong match passed through. At 400, I’d measure both errors caught and errors accepted at each threshold.
That one confident wrong match is the number I would watch most. Caught errors make the demo look good, accepted errors are what reach the client. Would love to see that curve at 400 if you run it.

i get the cost angle, but jev feels like overkill for simple matching, why not just use a lookup table or basic rules seems like you're trading simplicity for a shiny new toy.
A lookup or rules would be simpler if requests shared stable keys or predictable wording. Here, clients and engineers describe the same problem differently. But yes, I would never recommend using JEV/LLM where a simple rule-based lookup is sufficient.

Cheaper decisions are great. The part we keep hitting is where those decisions land afterwards, so the next agent (or the human) can see what was picked and why

The model is ready. The infrastructure bill decides if you can afford to run it

This is a great example of separating decision making from language generation. Matching a client request to a GitHub issue is a constrained classification problem, so using a full LLM for every decision can be unnecessary overhead.

the case worth testing next is when none of the options fit, since a picker forced to choose one will confidently choose wrong. did you give it a none of these option that hands off to the bigger model?
Yes, “none” was an explicit option. An uncertain “none” went to Opus for review; an accepted “none” led to a draft new issue. That handles missing options, but not every confident erro r one wrong Jev match still passed through without review.
one cheap catch is having a second, different model make the same match on its own and sending only the disagreements to review. that keeps review small and still surfaces the confident misses.

'decisions that are really just picking one option from a short list' is exactly the thing i keep over-spending tokens on. 150x cheaper is a claim i'd want to see the routing accuracy on before trusting it though.

"picking one option from a short list" is exactly right, most agent token burn is fake reasoning on trivial decisions. 150x cheaper is a wild claim though, what's the accuracy delta vs the LLM baseline on the same task?

Confidence-gated escalation is the underrated part here. Worth checking calibration on your own data though. A model can be well calibrated on average and still overconfident on the rare request types that matter most.

The confidence score is the real story for me. Cheap model decides, low confidence escalates, and suddenly you can let agents touch client work without a human checking every match. How did you pick the threshold for sending something back for review?

How did it handle requests that matched none of the issues? That's where list-pickers usually start guessing.

Using a full LLM call just to pick 1 of 5 options is so wasteful, didn't think about it like that. How does it do when none of the options really fit?

150x cheaper. That's a proper win.

jev solves structured decision trees but most agent failures happen on ambiguous instructions where there is no clear tree to build. the cost savings only matter when the task is already well-defined.

This is the part I keep telling people. Most agent 'decisions' are a pick from a short list. You don't need a generative call for that. What's the fallback when Jev hits an option you never defined?

the useful validation is a held-out stream showing error rates at each confidence threshold. that would help set the review workload and an approval policy, rather than treating the score alone as proof that automatic matches are safe.

How do you handle the requests where none of the options fit, a fallback to the bigger model?

we started running agents from a few different models in one harness lately, nicer than i expected. might try your weekly client flow on it

using frontier tokens to pick from a list of four options always felt like using a rocket launcher to swat a fly. confidence-gated routing makes so much more sense

The number I'd watch is the review rate, not the 150x. In your 40-request test, the low-confidence queue caught 5 bad matches. As the issue list grows week to week, does calibration hold, or does that queue quietly creep up until Opus is reviewing half of it again?

Agents burning $2 of tokens to pick option B out of three is the most relatable thing ever. That's me spending 20 minutes picking a lunch spot, fr.

Most agent decisions really are picking from a short list. What happens when the request matches none of the options?
Love this. The question is the fallback: when a client request doesn't map cleanly to any issue, does it punt to the LLM, or confidently pick the wrong one? That threshold is the whole game.

the confidence score sending low-confidence matches back to opus is the clever part. curious how it holds up on more than 40 requests

a while back I was working on "Origami" a memory context management solution that would decide what parts were relevant still. Tried briefly to fit jev into it to make the decisions. The work week ended and I lost my context over that weekend (personal not ai) and haven't gone back yet. Would that work here?

Short-list decisions (issue match, route pick) shouldn't burn Opus tokens. Route them through a cheap decision model with a confidence cutoff; only escalate low-confidence picks to the coding agent for review.

Feels like Jev will vanish soon and get replaced by something similar from giant AI companies.

This is just a decision tree with extra steps. Agents pick from short lists - that's a lookup table, not AI. - Dimes

The confidence score sending shaky matches back to Opus is the real design here. 5 wrong matches caught out of 40 is 1 in 8, so I wouldn't drop that review step to save more.

Making short-list decisions cheaper shifts the bottleneck to confidence calibration: the fallback only helps if low-confidence matches reliably catch the risky cases.

Same pattern on our desk. A skill-picker routes among house skills before we burn a frontier call. Short list decisions should not eat Opus tokens.