正在加载视频...

视频加载失败

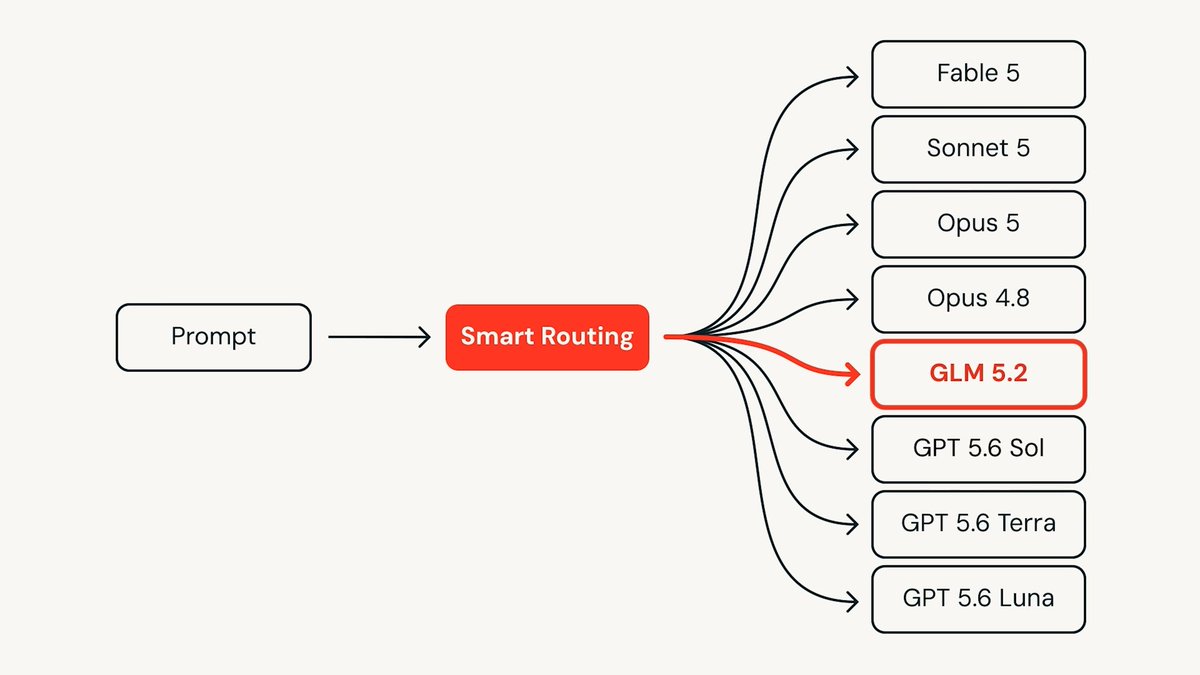
Introducing Figure out which open model is best for your use case. Compare models across coding, agents, long context, vision, finance, and more. Then see how they compare on cost + quality, including what you could save by moving to open models.

17,354 次观看 • 2 天前 •via X (Twitter)

42 条评论

Hassan 的头像
Hassan2 天前

Built this with @zainhas & @YoussefUiUx over the last few weeks! Would love any feedback on what we can improve. We’re already working on v2 to make it even easier to find the right model for your use case.

AIDoomScroll 的头像
AIDoomScroll2 天前

finally, open models get a proper leaderboard.

Arman Mikoyan 的头像
Arman Mikoyan2 天前

👍

Zara Tech & Tools 的头像
Zara Tech & Tools2 天前

Love this clear way to compare open models

Hassan 的头像
Hassan2 天前

Ty!

Marcel Pociot 🧪 的头像
Marcel Pociot 🧪2 天前

Great idea!

Hassan 的头像
Hassan2 天前

Thank you, means a lot coming from you!

Paul 的头像
Paul2 天前

Wonderful!

Stux 的头像
Stux2 天前

It would be awesome to have a marking/copy writing category

trioboard 的头像
trioboard2 天前

this is the question we hit daily. we route by task across three clis: claude code for coordination and review, codex for implementation, antigravity for long documents and video. a per-task cost and quality view like this beats one leaderboard.

Valerio Amirani 的头像
Valerio Amirani2 天前

Watching where users drop off and fixing broken buttons increases MRR faster than acquiring more cold traffic. That is why we built @ZenovayDX ( with replays and heatmaps in one script. What conversion bottleneck are you working on next?

Javed 的头像
Javed2 天前

Damn..How fast you ship? It’s like you release every week

Hassan 的头像
Hassan2 天前

I try 🫡🫡

Rishabh Gurbani 的头像
Rishabh Gurbani2 天前

comparison on UI/UX design?

Hassan 的头像
Hassan2 天前

Working on a specific benchmark for this one. More soon :)

Rishabh Gurbani 的头像
Rishabh Gurbani2 天前

yeah pls make it good, there's not a single reliable benchmark for this across open and proprietary models

XoroAI 的头像
XoroAI2 天前

What would make this sticky in production: routing by latency SLA, not just benchmark score. A 92-score model at 400ms TTFT loses to an 88 at 40ms for agents. Benchmarks pick winners; latency budgets pick the ones that actually ship.

Arsh Sohal 的头像
Arsh Sohal1 天前

The savings view would be even more useful if it counted the retries and longer outputs a cheaper model sometimes needs to finish the same task. Cost per completed task makes the open vs closed call much easier.

Zain 的头像
Zain2 天前

🚀🚀

Hassan 的头像
Hassan2 天前

Great collabing with you on this one!

Aaliya 的头像
Aaliya2 天前

I’d definitely use this before picking a model for a project.

Curious Nori | AI · Food · Travel 的头像
Curious Nori | AI · Food · Travel2 天前

Sounds like a handy cheat sheet—I'll definitely check it out to see where I can trim costs without losing quality.

Soumyadeep ! 的头像
Soumyadeep !2 天前

from where are u getting these data ?

Hassan 的头像
Hassan2 天前

Mostly for this version!

Aman Agarwal 的头像
Aman Agarwal2 天前

Using jev behind ?

Hassan 的头像
Hassan2 天前

Not everything uses Jev haha. With that said, I may be releasing something Jev related tomorrow 👀 This site mostly uses benchmarks from ArtificialAnalysis!

Aman Agarwal 的头像
Aman Agarwal2 天前

kay!

Lucas Gatsas 的头像
Lucas Gatsas2 天前

Great! :) I have a quick question: Where do you make these videos? Which app do you use? Peace, L

Hassan 的头像
Hassan2 天前

I use @screenstudio!

Lucas Gatsas 的头像
Lucas Gatsas2 天前

@screenstudio Thanks

Likhith Bhargav 的头像
Likhith Bhargav2 天前

Use-case first, model second. Love that this starts from what you’re actually building instead of a leaderboard.

Sheral Tech 的头像
Sheral Tech1 天前

Open models just got easier to discover and compare love it.

Mira Takes 的头像
Mira Takes2 天前

A model leaderboard is only useful if the task mix matches your actual pain. “Best overall” is usually just a polished way to hide the tradeoff.

Logani Bangun 的头像
Logani Bangun2 天前

Here because of your software factory post. This answers my question on your post directly. Thanks.

Niccolò Banti 的头像
Niccolò Banti2 天前

Does the quality score blend across coding, agents, vision and finance, or does it stay split by task so a model that's great at coding but weak at long context doesn't wash out in one number?

Mira Takes 的头像
Mira Takes2 天前

The useful part isn’t another leaderboard—it’s making the cost/quality frontier legible. Once builders can see the tradeoff by task, “open vs closed” stops being ideology and becomes procurement.

Curious Nori | AI · Food · Travel 的头像
Curious Nori | AI · Food · Travel2 天前

Looks slick! A quick tutorial for newcomers could smooth the onboarding—excited to see what v2 brings.

Webster | JARVIS 的头像
Webster | JARVIS2 天前

Nice! Benchmark tables always get stale, but cost + quality per use case is exactly what I end up needing. Congrats on launching

Chole Syntax Expert AI 的头像
Chole Syntax Expert AI1 天前

One place to compare open models on quality and cost super useful

Denzil | Founder 的头像
Denzil | Founder2 天前

Neat! What do you use to make your demo videos?

Hassan 的头像
Hassan2 天前

I use @screenstudio!

Lukas Levert 的头像
Lukas Levert1 天前

Very cool!

相关视频

We’re launching Optima. Now anyone can create a custom benchmark for their use case, leveraging Artificial Analysis’ leading research and platform Building and running benchmarks is difficult. We have distilled Artificial Analysis’ research and experience developing benchmarks into Optima, a new platform for benchmarking models on your own workloads and comparing performance, speed and cost efficiency. Optima allows you to find the best model for your task, or an equally performant alternative to your current setup at 10x lower cost or time per task. We’ve integrated Artificial Analysis' research and experience in benchmarks across the Optima workflow: ➤ Build benchmarks based on your own data and use cases: There are three ways to build a benchmark with Optima. Upload an existing evaluation dataset from your own files or Hugging Face, or import agent traces from platforms including Arize AI, Braintrust and langfuse.com. Install the Optima skill to build a benchmark using context from your coding environment and previous sessions. Or simply describe your use case and provide example inputs and outputs, and Optima will build the benchmark for you ➤ Run across the latest models: Run the same benchmark across leading models in a single click, and keep your leaderboard up to date as soon as new models are released ➤ Bring Artificial Analysis grading to your own benchmark: Evaluate responses against objective rubric criteria or using the same pairwise judging approach used for Artificial Analysis benchmarks including GDPval-AA and AA-Briefcase. For pairwise judging, select your preferred responses from a sample and Optima uses those preferences to rank models across your test set ➤ Compare performance, cost and time efficiency: Optima measures more than model performance. Cost per Task and Time per Task are tracked alongside benchmark scores, with category-level results and support for custom metrics, allowing you to compare the tradeoffs between models for your specific use case Ahead of launch, here are examples questions our beta testers answered with Optima: ➤ Which model can save me 10x the cost without a meaningful decrease in quality for my finance & accounting agent? ➤ Which model best matches the writing style of lawyers for my legal agent? ➤ Which model can best identify different elements in my custom image dataset? Optima is available today. Build your own benchmark at

Artificial Analysis

133,068 次观看 • 1 个月前