Loading video...

Video Failed to Load

Go Home

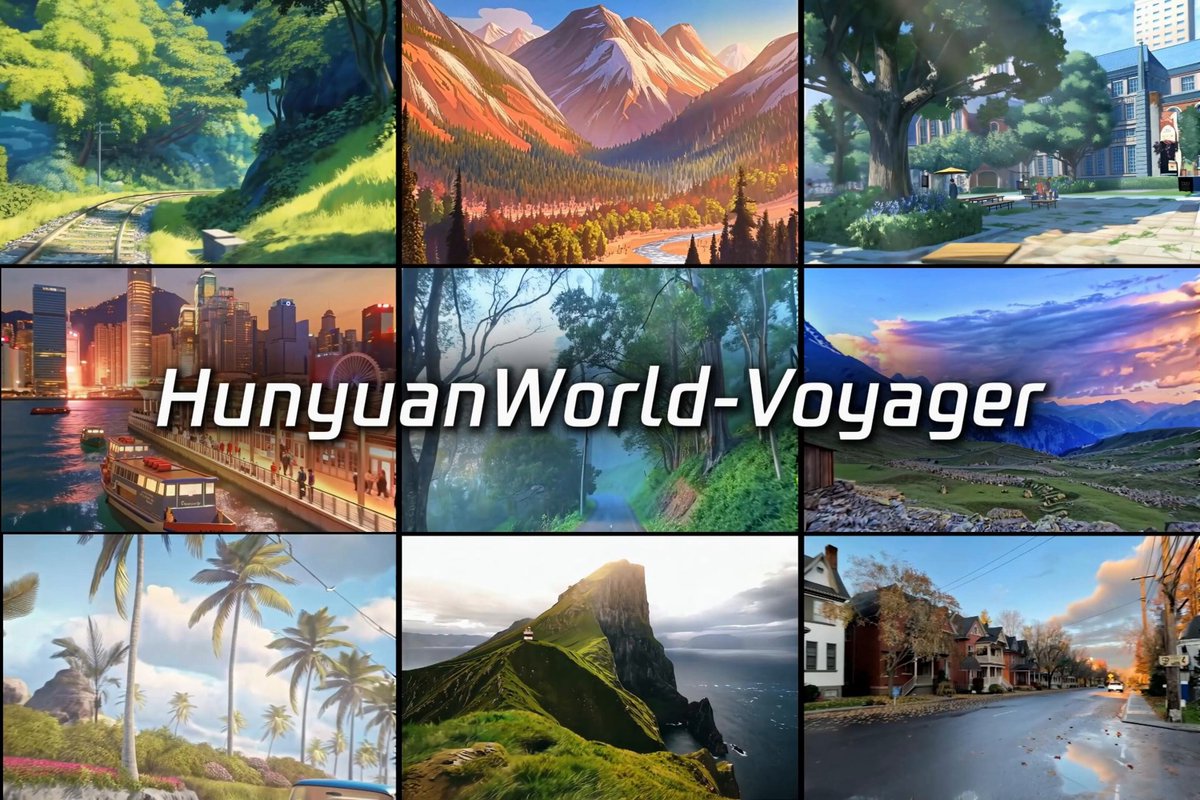
🚀 Introducing Hy-Nomas: An Open Source Free-Form Interactive Video World Model Key Features: * Free-form interaction with text prompts and camera trajectories * Long-horizon generation with world memory * Lightweight LoRA adaptation for specialized domains such as robotics * Optimized for Inference on Consumer GPUs Test it and drop...

41,195 views • 23 hours ago •via X (Twitter)

20 Comments

Vishal Singh's profile picture
Vishal Singh21 hours ago

Would have been amazing if it worked on low VRAM but requires 24GB VRAM out of the box. And yes 24GB is better than previous models that require supercomputers to run, but it's still not enough. These models should support lower VRAM like 16GB or ideally even lower at launch.

Dima Nurm's profile picture
Dima Nurm19 hours ago

@anabology take a look

xabz's profile picture
xabz22 hours ago

world memory in a video model is the part that actually matters

PASSED K1NG's profile picture
PASSED K1NG23 hours ago

Grateful for every open-source model, even if it hasn't quite reached the cutting edge yet

Prompt Heat's profile picture
Prompt Heat22 hours ago

we need the best cheap strongest model and maybe free in your code desktop app :D LOL

Apollo's profile picture
Apollo23 hours ago

Tencent’s AI ecosystem Keep evolving and expanding. From llms to world models, they keep reasong ai solutions evwn if not frontier

Sahil Sangani 🇮🇳/acc's profile picture
Sahil Sangani 🇮🇳/acc21 hours ago

can i get access?

Zoraya Ai's profile picture
Zoraya Ai22 hours ago

Open-source world models with persistent memory and consumer GPU support could make interactive video generation far more accessible

Dima Nurm's profile picture
Dima Nurm19 hours ago

Awesome—today is a day for releases from the East; really cool. 👍

👁️M1nd 3xp4nd3r👁️'s profile picture
👁️M1nd 3xp4nd3r👁️21 hours ago

Ohhhhhhh you all just changed visuals and something I been wanting to experiment for years this is amazing

Ton🇹🇭's profile picture
Ton🇹🇭22 hours ago

😉

Alyar AI's profile picture
Alyar AI21 hours ago

Optimized for consumer GPUs is a big win. Powerful AI should be more accessible! 💯

Clara AI | Tools & Updates's profile picture
Clara AI | Tools & Updates22 hours ago

Free form text and camera control on consumer hardware is solid

Kyrzel ⚔️'s profile picture
Kyrzel ⚔️19 hours ago

The future of @makooor

NeuralLoot's profile picture
NeuralLoot23 hours ago

How it fits on one RTX 4090: DiT weights and the KV cache are stored in INT8, the decoder runs in FP8, and only 18 past latent frames stay on the GPU while the rest of the world's history waits on CPU. Same 8-step schedule, still 720x1280 at 24 FPS.

SynnJJ's profile picture
SynnJJ21 hours ago

Just amazing, will try it right away💛💛💛

Squirrel's profile picture
Squirrel20 hours ago

What is this

J A Z I I's profile picture
J A Z I I18 hours ago

is there API so I can use???

Camila Rivera's profile picture
Camila Rivera19 hours ago

Open-source world models are taking AI video to the next level

lklz's profile picture
lklz23 hours ago

流量

Related Videos

We've officially released and open-sourced HunyuanImage 2.1, our latest text-to-image model. The new model delivers on our commitment to balancing performance and quality. With native 2K image generation, HunyuanImage 2.1 is an advanced open-source text-to-image model.🎨 ✨ New in 2.1: 🔹Advanced Semantics: Supports ultra-long and complex prompts of up to 1000 tokens, and precisely controls the generation of multiple subjects in a single image. 🔹Precise Chinese and English Text Rendering with seamless image–text integration: The model naturally integrates text into images, making it suitable for a wide range of applications such as product covers, illustrations, and poster design to meet the needs of various fields. 🔹Rich Styles and High Aesthetic: Capable of generating images in various styles—including photorealistic portraits, comics, and vinyl figures—it delivers outstanding visual appeal and artistic quality. 🔹High-Quality Generation: Efficiently produces ultra-high-definition (2K) images in the same time other models take to generate a 1K image. HunyuanImage 2.1 uses two text encoders: a multimodal large language model (MLLM) to improve the model's image and text alignment capabilities, and a multi-language character-aware encoder to improve text rendering capabilities. The model is a single- and double-stream diffusion transformer with 17B parameters. We've also open-sourced the weights of the the accelerated version with meanflow which reduces inference steps from 100 to just 8, and PromptEnhancer, the first industrial-grade rewriting model that enhances your prompts for more nuanced and expressive image generation. Now, creators turn complex ideas—like posters with slogans or multi-panel comics—into visuals faster than ever. We’re just getting started. Stay tuned for our native multimodal image generation model coming soon. 🌐Website: 🔗Github: 🤗Hugging Face: ✨Hugging Face Demo:

Tencent Hy

89,430 views • 1 year ago

We’re excited to announce the release and open-source of HunyuanImage 3.0 — the largest and most powerful open-source text-to-image model to date, with over 80 billion total parameters, of which 13 billion are activated per token during inference.The effect is completely comparable to the industry’s flagship closed-source model.🚀🚀🚀 HunyuanImage 3.0 originates from our internally developed native multimodal large language model, with fine-tuning and post-training focused on text-to-image generation. This unique foundation gives the model a powerful set of capabilities: ✅Reason with world knowledge ✅Understand complex, thousand-word prompts ✅Generate precise text within images Different from traditional DiT architecture image generation models, HunyuanImage 3.0’s MoE architecture uses a Transfusion-based approach to deeply couple Diffusion and LLM training for a single, powerful system. Built on Hunyuan-A13B, HunyuanImage 3.0 was trained on a massive dataset: 5 billion image-text pairs, video frames, interleaved image-text data, and 6 trillion tokens of text corpora. This hybrid training across multimodal generation, understanding, and LLM capabilities allows the model to seamlessly integrate multiple tasks. Whether you're an illustrator, designer, or creator, this is built to slash your workflow from hours to minutes. HunyuanImage 3.0 can generate intricate text, detailed comics, expressive emojis, and lively, engaging illustrations for educational content. The current release focuses solely on text-to-image generation and future updates will include image-to-image, image editing, multi-turn interaction, and more. 👉🏻Try it now: 🔗GitHub: 🤗Hugging Face:

Tencent Hy

413,296 views • 1 year ago