Video yükleniyor...

Video Yüklenemedi

Ana Sayfaya Dön

📢 Lyra: Generative 3D Scene Reconstruction via Video Diffusion Model Self-Distillation Got only one or a few images and wondering if recovering the 3D environment is a reconstruction or generation problem? Why not do it with a generative reconstruction model! We show that a camera-conditioned video diffusion model can...

66,918 görüntüleme • 1 yıl önce •via X (Twitter)

38 Yorum

Sherwin Bahmani profil fotoğrafı
Sherwin Bahmani1 yıl önce

Previous work (left) trains image-to-3D models using real-world datasets with limited diversity. In contrast, we propose a self-distillation framework (right) for generative 3D scene reconstruction. Specifically, a pre-trained camera-controlled video diffusion model (GEN3C) with its RGB decoder output (teacher) supervises the rendering of the 3DGS decoder (student). Using a video model pre-trained on large-scale real-world 2D video data allows us to provide diverse and potentially infinite multi-view supervision.

Sherwin Bahmani profil fotoğrafı
Sherwin Bahmani1 yıl önce

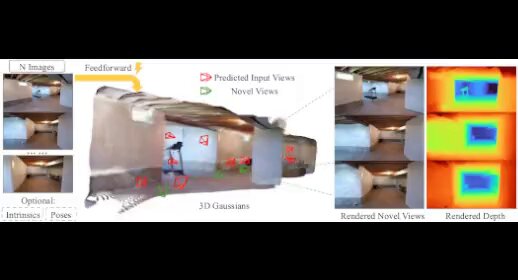
Our model generates 3DGS scenes from a single input image in a feed-forward manner generalizing across a wide range of scenarios., without the need for per-scene optimization.

Sherwin Bahmani profil fotoğrafı
Sherwin Bahmani1 yıl önce

Moreover, our framework easily extends to feed-forward 4D scene generation from a single input video.

Sherwin Bahmani profil fotoğrafı
Sherwin Bahmani1 yıl önce

Our approach seamlessly generalizes to full 3D scene generation from a single real image, without ever being trained on real-world data.

Sherwin Bahmani profil fotoğrafı
Sherwin Bahmani1 yıl önce

The generated 3D Gaussians can then be exported into into NVIDIA Isaac Sim based on 3DGUT to simulate humanoid robots in generated environments.

Sherwin Bahmani profil fotoğrafı
Sherwin Bahmani1 yıl önce

Joint work with @TianchangS @jiawei6_ren @huangjh_hjh Yifeng Jiang @Haithem_Turki @taiyasaki @davelindell @ZGojcic @FidlerSanja @HuanLing6 @JunGao33210520 @xuanchi13

Sherwin Bahmani profil fotoğrafı
Sherwin Bahmani1 yıl önce

@jiawei6_ren @huangjh_hjh @Haithem_Turki @taiyasaki @DaveLindell @ZGojcic @FidlerSanja @HuanLing6 @JunGao33210520 @xuanchi13 Check out this very related work Bolt3D ( at ICCV next month by @StanSzymanowicz @jasonyzhang2 @_pratul_ @RuiqiGao @ArthurBrussee @holynski_ @rmbrualla @jon_barron @philipphenzler

Sherwin Bahmani profil fotoğrafı
Sherwin Bahmani1 yıl önce

@jiawei6_ren @huangjh_hjh @Haithem_Turki @taiyasaki @DaveLindell @ZGojcic @FidlerSanja @HuanLing6 @JunGao33210520 @xuanchi13 @StanSzymanowicz @jasonyzhang2 @_pratul_ @RuiqiGao @holynski_ @rmbrualla @jon_barron @philipphenzler Special thanks to @robrombach @andi_blatt and the rest of the team at @bfl_ml for open-sourcing FLUX ( We use FLUX to generate high-quality input images and lift them into 3D.

Matthias Niessner profil fotoğrafı
Matthias Niessner1 yıl önce

Amazing work!

Sherwin Bahmani profil fotoğrafı
Sherwin Bahmani1 yıl önce

Thanks Matthias 🍻

Kai He profil fotoğrafı
Kai He1 yıl önce

Strong 👍👍🥳

Sherwin Bahmani profil fotoğrafı
Sherwin Bahmani1 yıl önce

Not as strong as you 😌

Eduard Zamfir profil fotoğrafı
Eduard Zamfir1 yıl önce

Uff 😮‍💨 sky is the limit! 🚀

Sherwin Bahmani profil fotoğrafı
Sherwin Bahmani1 yıl önce

Danke du Spruecheklopfer 🤪

Oliver Hahn profil fotoğrafı
Oliver Hahn1 yıl önce

Machine! Congrats 🚀

Sherwin Bahmani profil fotoğrafı
Sherwin Bahmani1 yıl önce

Danke Bro 😎

Lily Goli profil fotoğrafı
Lily Goli1 yıl önce

looks amazing!! 🎉

Sherwin Bahmani profil fotoğrafı
Sherwin Bahmani1 yıl önce

Thanks Lily 😊

Stephen J. Caggiano profil fotoğrafı
Stephen J. Caggiano1 yıl önce

🔥❤️👏🏼

Ziya Erkoç profil fotoğrafı
Ziya Erkoç1 yıl önce

Congrats, Sherwin!🎉🎉

Sherwin Bahmani profil fotoğrafı
Sherwin Bahmani1 yıl önce

Thanks Ziya 🫡

Tuan Ngo profil fotoğrafı
Tuan Ngo1 yıl önce

Amazing!!! Congrats Sherwin

Sherwin Bahmani profil fotoğrafı
Sherwin Bahmani1 yıl önce

Thanks big guy 🙏

Ison Ward profil fotoğrafı
Ison Ward1 yıl önce

Cool!That looks like a good time

Sai Tedla profil fotoğrafı
Sai Tedla1 yıl önce

This is insane.

Phil Franco profil fotoğrafı
Phil Franco1 yıl önce

that looks cool!

Yuyang Zhao profil fotoğrafı
Yuyang Zhao1 yıl önce

Amazing work! Congrats, Sherwin!

Sherwin Bahmani profil fotoğrafı
Sherwin Bahmani1 yıl önce

Thanks Yuyang 🤪

Hadi Alzayer profil fotoğrafı
Hadi Alzayer1 yıl önce

Very cool work! Congrats on the release

Sherwin Bahmani profil fotoğrafı
Sherwin Bahmani1 yıl önce

Thanks Hadi 😊

:3 profil fotoğrafı
:31 yıl önce

This is over 20 years ago:

Felix Taubner profil fotoğrafı
Felix Taubner1 yıl önce

The 4D 🐐 🤩

Sherwin Bahmani profil fotoğrafı
Sherwin Bahmani1 yıl önce

No, you are the 4D 🐐😮‍💨

Mohamad Shahbazi profil fotoğrafı
Mohamad Shahbazi1 yıl önce

Really cool work and amazing results Sherwin! :) Was wondering, how sensitive the 3DGS decoder is to the multivew inconsistencies?

Sherwin Bahmani profil fotoğrafı
Sherwin Bahmani1 yıl önce

Thanks! We learn to smoothen inconsistencies with LPIPS loss. Obviously, a more consistent diffusion model will make it easier to get consistent output. The current viewpoint change is mainly limited because the diffusion output gets more and more inconsistent far away from the input view. Hope to improve that!

Ethan Weber profil fotoğrafı
Ethan Weber1 yıl önce

Congrats! I really like the ideas here. 🙂

Sherwin Bahmani profil fotoğrafı
Sherwin Bahmani1 yıl önce

Thanks Ethan 😊

Andrew Guo profil fotoğrafı
Andrew Guo7 ay önce

wow! this is cool

Benzer Videolar

DreamCraft3D: Hierarchical 3D Generation with Bootstrapped Diffusion Prior paper page: present DreamCraft3D, a hierarchical 3D content generation method that produces high-fidelity and coherent 3D objects. We tackle the problem by leveraging a 2D reference image to guide the stages of geometry sculpting and texture boosting. A central focus of this work is to address the consistency issue that existing works encounter. To sculpt geometries that render coherently, we perform score distillation sampling via a view-dependent diffusion model. This 3D prior, alongside several training strategies, prioritizes the geometry consistency but compromises the texture fidelity. We further propose Bootstrapped Score Distillation to specifically boost the texture. We train a personalized diffusion model, Dreambooth, on the augmented renderings of the scene, imbuing it with 3D knowledge of the scene being optimized. The score distillation from this 3D-aware diffusion prior provides view-consistent guidance for the scene. Notably, through an alternating optimization of the diffusion prior and 3D scene representation, we achieve mutually reinforcing improvements: the optimized 3D scene aids in training the scene-specific diffusion model, which offers increasingly view-consistent guidance for 3D optimization. The optimization is thus bootstrapped and leads to substantial texture boosting. With tailored 3D priors throughout the hierarchical generation, DreamCraft3D generates coherent 3D objects with photorealistic renderings, advancing the state-of-the-art in 3D content generation.

AK

161,530 görüntüleme • 3 yıl önce

📢📢 𝐀𝐯𝐚𝐭𝟑𝐫 📢📢 Avat3r creates high-quality 3D head avatars from just a few input images in a single forward pass with a new dynamic 3DGS reconstruction model. Video: Project: Our core idea is to make Gaussian Reconstruction Models animatable. We find that a simple cross-attention to an expression code sequence is already sufficient to model complex facial expressions. We then incorporate position maps from DUSt3R and feature maps from Sapiens to facilitate the prediction task. While DUSt3R's position maps act as a pixel-aligned initialization for the Gaussians' positions, the Sapiens feature maps help the cross-view transformer to match corresponding image tokens in the 4 input images. One major challenge in creating a 3D head avatar from smartphone images comes from inconsistent facial expressions when the subject could not remain perfectly static during the capture. We eliminate this static requirement by simply showing our model input images with different facial expressions during training. This technique makes our model robust to inconsistent input images later on. Finally, we show that despite the model has been trained with 4 input images, one can even create a 3D head avatar when only a single image is available. To achieve this, we employ a pre-trained 3D GAN to lift the single image to 3D and then render the 4 input images for our model. This allows us to create 3D head avatars from single images and even highly out-of-distribution examples like AI generated faces, paintings or statues. Great work by Tobias Kirschstein from his internship at Meta with Javier Romero, Artem Sevastopolsky, and Shunsuke Saito

Matthias Niessner

74,863 görüntüleme • 1 yıl önce