正在加载视频...

视频加载失败

PowerInfer - a high-speed inference engine for deploying LLMs locally. Just came across this super interesting project on speeding up inference. It's not MoE but it's a simple approach that exploits the high locality in LLM inference to design a GPU-CPU hybrid inference engine. Hot-activated neurons are preloaded onto...

261,622 次观看 • 2 年前 •via X (Twitter)

10 条评论

elvis 的头像
elvis2 年前

source: github:

Adam Pippert 的头像
Adam Pippert2 年前

This is HUGE. I always suspected that there would be a way to break up the architecture of a model to alleviate the GPU cost and availability bottleneck. Will play with this on LLaMa2, but highly anticipating Mistral-7B.

Hamid R. Darabi 的头像
Hamid R. Darabi2 年前

It's very interesting! 11.69x improvement over llama.cpp sounds a lot, given that it's already super efficient. Are you sure it's not 11.7%? Even that could be a good result.

Loki (cute/acc) 的头像
Loki (cute/acc)2 年前

I almost tried this before I realized it's one more model exchange format 🥲 ".powerinfer.gguf" Can't all of you just use onnx and move on in life? 😭

catid (e/acc) 的头像
catid (e/acc)2 年前

Nice I was working in this direction recently noting the same things. 12x speedup is very respectable compared to 8x being the best so far achieved by any one approach (e.g. pruning/quantization)!

Filippo Pedrazzini 的头像
Filippo Pedrazzini2 年前

15 GiBs of weights? And this is supposed to run on Consumer Devices?! 🧐

Medium Boss - 70b_Float16.Q8.gguf 的头像
Medium Boss - 70b_Float16.Q8.gguf2 年前

The week I got a new PC with a beefy CPU. Fucking nice.

Sahar Mor 的头像
Sahar Mor2 年前

Paper tl;dr

s3nh 的头像
s3nh2 年前

Fastest bookmark 🤫🤫🤫

Ruairi 的头像
Ruairi2 年前

Noob question, is this just for the activation function or is it also cutting down the number of entries for GPU matrix multiplication as well?

相关视频

I had to test it myself to believe this unreal inference speed. 3,000 tokens/s for 1 user on standard datacenter GPUs. They leveraged a hidden efficiency gap in how GPUs generate tokens. Kog just achieved 3,000 tokens/s on 8× AMD MI300X GPUs and 2,100 on 8× NVIDIA H200 (FP16, no speculative decoding). Their tech preview is on a 2B model, and they show how their techniques will scale to large frontier MoE models at similar speeds. That's a huge number because normal low-batch GPU decoding for 2B to 8B models is usually closer to 100 to 300 tokens/s per request, so Kog is claiming something like a 10X to 30X jump in the speed one user actually feels. Their trick: they are getting the speed by treating LLM decoding as a memory streaming problem, not mainly a math problem. For 1 user at batch size 1, the GPU is not doing big, efficient matrix-matrix work like in training or large-batch serving; it is repeatedly pulling the model’s active weights from high-bandwidth memory for each new token, so speed depends on how smoothly those weights keep flowing. Normal inference stacks keep breaking that flow. They run many separate GPU programs for different parts of the model, move intermediate results through memory, wait at synchronization points, talk back to the CPU for scheduling or sampling, and then repeat this token after token. Kog’s answer is to co-design 3 things that are usually tuned separately: the runtime, the low-level GPU code, and the model architecture. The biggest engineering move is the monokernel, where the whole decode pass runs as 1 persistent GPU-resident program, including sampling, so the system does not keep stopping for kernel launches, CPU scheduling, and intermediate memory round trips. They also rebuilt synchronization, because their own measurements say grid sync was eating around 35% of token-generation time; instead of making every compute unit wait at a broad barrier, each unit waits only for the exact data it needs. On AMD MI300X, they also map memory access around the chiplet layout, because memory latency changes depending on which die makes the request. Then their Laneformer model uses Delayed Tensor Parallelism, which lets cross-GPU communication happen in the background instead of blocking every layer.

Rohan Paul

13,282 次观看 • 3 个月前

UC Berkeley just open-sourced FreeToken. (2–4x faster local LLM inference than Ollama) the results are wild: - Qwen3.6-35B on an 8GB GPU at 39.3 tokens/s - DeepSeek-V4-Flash 284B on a 32GB GPU at 22 tokens/s - GLM-5.2 753B on a 96GB GPU at 14.9 tokens/s a 35B model at 16-bit precision needs about 70GB just for its weights. even at 4 bits it is close to 18GB, and FreeToken serves it on an 8GB GPU. let me explain how: all three models mentioned above are Mixture-of-Experts, and that is what FreeToken takes advantage of. each layer holds hundreds of separate experts plus a small router that picks a few of them per token. Qwen3.6-35B activates roughly 3B of its 35B parameters per token. DeepSeek-V4-Flash picks 6 of 256 experts per layer, so 13B of its 284B run at a time. so compute was never the bottleneck. the weights a single step touches fit comfortably on a consumer GPU. every expert the router might pick still has to exist somewhere. they sit in system RAM, and the GPU keeps a cache of the ones the model has been using recently. so everything comes down to what happens when the router picks an expert that is not on the GPU. there are two ways to serve that miss: 1. copy it over PCIe and run it on the GPU 2. run it on the CPU, where it already lives both read from the same system memory, so they compete for one pool of bandwidth instead of adding to each other. existing engines pick one option and freeze it when the model loads. but routing changes on every token, so a fixed choice misses most of what the model asks for. FreeToken measures both bandwidths on your machine and splits each step's misses between the two paths in proportion. the GPU and CPU results then merge exactly, with no approximation. two machines with the same GPU can end up wanting opposite strategies, which I did not expect. a 5090 in a gaming desktop should push nearly everything over PCIe, while an 8GB laptop is better off computing most misses on the CPU. none of that is readable off a spec sheet, so the engine profiles it once per machine. the second half of the design is about agents. coding agents constantly rewrite their own history, and every edit normally forces thousands of tokens back through prefill. FreeToken saves its checkpoints at the exact boundaries agent frameworks cut on, so it only reprocesses the new part. its slowest first token stays under 44 seconds, while llama.cpp peaks at 232 and KTransformers at 946. it serves the OpenAI and Anthropic APIs under Apache 2.0, so Claude Code and Codex can point at it directly. releasing weights publicly decides who can download a model, not who can afford to run one. frontier open models keep shipping, and running them still assumes a rented cluster. meanwhile there are over a hundred million consumer machines with discrete GPUs sitting mostly idle. closing that gap was never a hardware problem, and work like this is what turns open weights into something you can actually use. paper: repo: almost every idea in this post, from why memory bandwidth decides the outcome to why moving weights costs more than computing on them, comes straight out of how a GPU is built. I wrote a detailed primer on that. the article is quoted below.

Akshay 🚀

343,270 次观看 • 1 个月前

Dylan Patel on the importance of memory and storage Two key quotes: "An $NVDA GPU is faster than an $AMD GPU in most cases, but because AMD GPUs have more memory, they can outperform Nvidia in certain workloads." “It is a difficult, multivariable problem. Generally, you need the best GPU, such as a GB300, but you also need the best storage solutions. I will not spoil who comes out on top, but storage solutions matter a lot, memory solutions matter a lot, and frontend networking also matters significantly" Full Quote: “We have over $80 million of compute: GPUs from $NVDA and $AMD, TPUs from Google, and Trainium from Amazon. We constantly run this benchmark using the newest inference engines, drivers, PyTorch versions, and other software. It runs every day through automated CI across the latest Chinese models from GLM, Zhipu, Moonshot, Kimi, Alibaba, and others. Initially, when we were benchmarking the differences between these chips, inference engines, and parallelism schemes, we used fixed context lengths. But with Agent X, we have now analyzed more than $5 million worth of Claude Code traces. This is real production traffic that users have donated to us, combined with internally generated data, so we now understand what an actual agent workload looks like. When we implement those workloads and run the benchmarks, it turns out that the chip you are using is very important, but how you handle memory offload can be even more important. An Nvidia GPU is faster than an AMD GPU in most cases, but because AMD GPUs have more memory, they can outperform Nvidia in certain workloads. Similarly, you can use a less powerful GPU with a much better storage solution and outperform the best GPU when it lacks those solutions. Simply buying the newest GPU does not necessarily give you the best inference economics. You need to layer in other innovations, including storage and memory.” Interviewer: “Who is the top player on your chart? Can you tell us?” Dylan Patel: “It is a difficult, multivariable problem. Generally, you need the best GPU, such as a GB300, but you also need the best storage solutions. I will not spoil who comes out on top, but storage solutions matter a lot, memory solutions matter a lot, and frontend networking also matters significantly.”

Daniel Romero

48,894 次观看 • 2 个月前

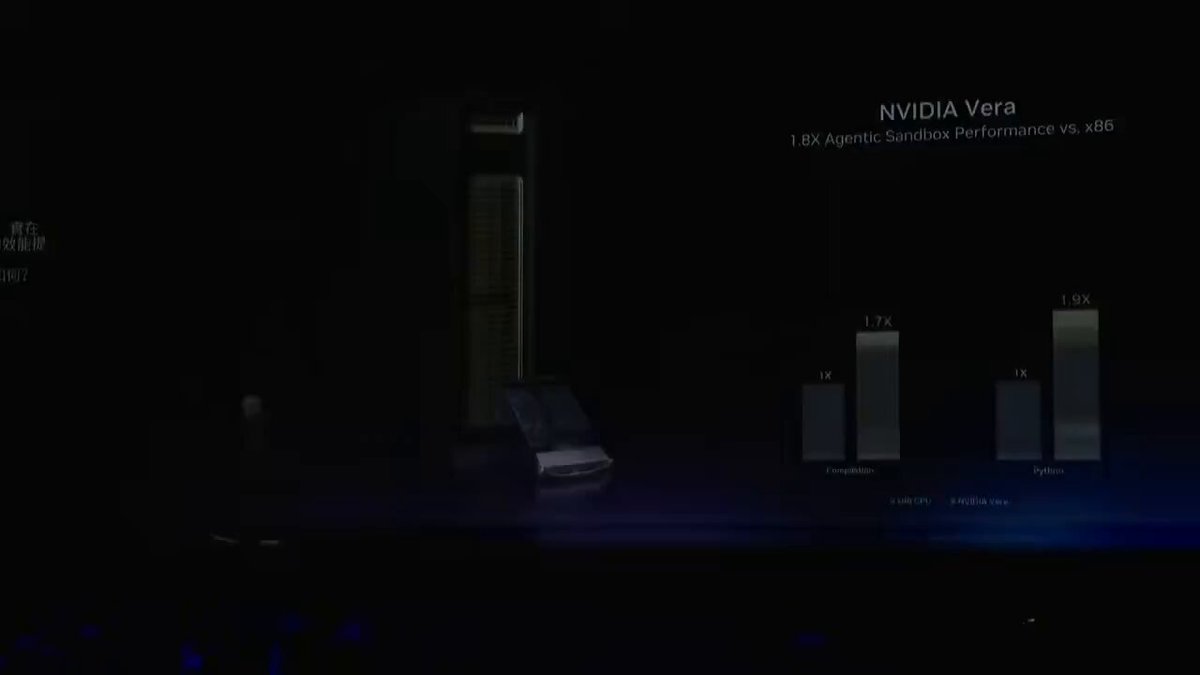
Jensen Huang just identified the next $200 billion market (Save this). The shift starts with a observation about agentic AI that changes everything about infrastructure. In the era of training and inference, the GPU was everything while CPU was a traffic cop, scheduling work, managing memory, dispatching tasks while the GPU did the heavy lifting. Agentic AI breaks that model entirely. An AI agent does not just run a single inference pass but rather it plans, calls tools, executes code in sandboxes, retrieves data from multiple sources and loops through complex multi-step reasoning sequences often thousands of times per second at scale. Every one of those operations runs through the CPU and the GPU sits idle waiting for the CPU to prepare the next task, supply the right context and execute the retrieval and tool calling logic fast enough to keep the accelerators fed. The CPU is now the conductor and the GPU is the orchestra and the bottleneck is the conductor falling behind. This is showing up in production AI factory utilization right now, which is exactly why Jensen built Vera from scratch rather than licensing x86. Vera achieves 40% lower peak memory latency than x86, 50% faster core to core communication, and 1.8 times the agentic sandbox performance of current x86 processors on a purpose-built architecture designed around the agentic loop. Now here is where the investment thesis gets interesting. The obvious beneficiary is Nvidia itself, and that thesis is real. Nvidia's CFO has guided for nearly $20 billion in Vera CPU revenue this fiscal year alone, a market Nvidia had zero presence in just three years ago. Intel held 60% of server CPU market share as recently as Q4 2025 and that transition is now happening at a pace Intel structurally cannot respond to. But the deeper question is, what architecture is Vera actually built on? Vera's Olympus cores are ARM compatible and every single Vera CPU deployed in every Vera Rubin rack in every data center in the world runs on ARM architecture. And ARM Holdings collects a royalty on every one of them. ARM does not make chips but rather licenses the instruction set architecture and CPU core designs that others build on top of. Every time Nvidia ships a Vera CPU, every time a hyperscaler deploys a Vera Rubin rack, every time an enterprise qualifies Vera for their AI factory, ARM earns a royalty. The secular tailwind here is almost perfectly constructed for ARM's business model. Amazon's Graviton, Microsoft's Cobalt, Google's Axion, Apple's silicon stack, and Qualcomm's data center push all run on ARM. And now Nvidia's Vera, which is projected to displace Intel as the largest server CPU supplier by revenue in a single fiscal year, is ARM. ARM's royalty rate on high end server chips is estimated at roughly 1 to 2% of chip selling price. At $5,000 per Vera CPU and 4 million units projected for FY2027, that is a royalty line growing from near zero to potentially $400 million to $800 million annually from Nvidia's data center CPU business alone before counting Amazon, Microsoft, Google, Apple, and Qualcomm. The total ARM addressable royalty base across all the silicon it already licenses is compounding at a rate that the current $130 billion market cap does not fully reflect. Jensen's CPU thesis is the most underappreciated catalyst in ARM's fundamental story, and the royalty compounding has barely started. Come join Milk Road Pro and get our full ARM royalty model and our entire AI trade thesis. Link below!

Milk Road AI

11,819 次观看 • 3 个月前

Dylan Patel of SemiAnalysis says a worse GPU with better storage and memory now beats the best chip without them, so buying the newest GPU alone no longer wins inference. So, an AMD GPU with more memory can outperform Nvidia in some cases. "So what we have is we have over $80 million of compute, GPUs from Nvidia, AMD, TPUs from Google, Trainium from Amazon, and we run this benchmark constantly on the newest inference engine, newest drivers, newest PyTorch version, whatever it is." "Every day it runs on an automated CI, and we run it on all the latest Chinese models, from GLM, Zhipu, Moonshot, Kimi, Alibaba, all these models we run." "Initially, when we were benchmarking the difference between these chips and different engines, different schemes for parallelism, we were just running it fixed context length." "But now with Agent X, we've analyzed over $5 million worth of Claude Code traces. This is real production traffic that people have donated to us as well as internally generated. Now we know what the actual agent workload looks like." "And then as we implement that and run those benchmarks, it turns out yes, the chip you're using is very important, but now even more important is how are you handling this memory offload?" "And so while an Nvidia GPU is faster than an AMD GPU in most cases, because AMD GPUs have more memory, they actually end up outperforming in some cases." "Or you can have a worse GPU, but a much better storage solution, and now you can outperform what the best GPU can do without those solutions. So just buying the newest and latest GPU alone doesn't get you the best inference economics." "Actually, you need to layer in all these other innovations including storage and memory." [ Who's the top player on your chart? ] "That really is a difficult multivariable problem. And generally that means you need to have, yes, you need to have the best GPU, a GB300, but you also need to have the best storage solutions. And so I won't spoil who's the best right here, but I will say that storage solutions matter a lot and memory solutions matter a lot, as does your front-end networking. That matters a lot."

Fireside Alpha

178,673 次观看 • 2 个月前

Etched is deploying two new technologies in chip design: low-voltage inference and cluster-scale memory. CEO Gavin Uberti says they'll make their chips much more power-efficient and way, way faster than today's leading GPUs. He breaks it down: "We looked at a lot of early research directions, and we realized the key things that models need are way more compute and way faster memory." "If you think about inference, there are two key parts: prefill and decode. For prefill, it's a compute-bound problem. You need to have more FLOPS, more operations per second on each of your chips." "On our GPU, the bottleneck's actually thermals. You can't really run a GPU at more than around 50% of what it could theoretically do, or it'll melt." "So we're using a new technology today called low-voltage inference to try to solve this problem. You bring the voltage of the chip down dramatically, which allows us to have way, way better efficiency in terms of how much power is drawn per unit of math, and thus fit way way more flops onto the chip..." "For decode, it's all about bandwidth. Not just bandwidth on a chip, but bandwidth across your cluster. That's why we have this technology we call cluster-scale memory. It reduces the amount of time it takes to communicate from one chip to another dramatically." "As a result we can go use all of our HBM, HBM bandwidth, SRAM, SRAM bandwidth, and our scale-up domain as a single coherent pool. And that means if you're a user, you can go get much faster tokens per second, while still keeping your costs low."

TBPN

20,404 次观看 • 2 个月前