Загрузка видео...

Не удалось загрузить видео

На главную

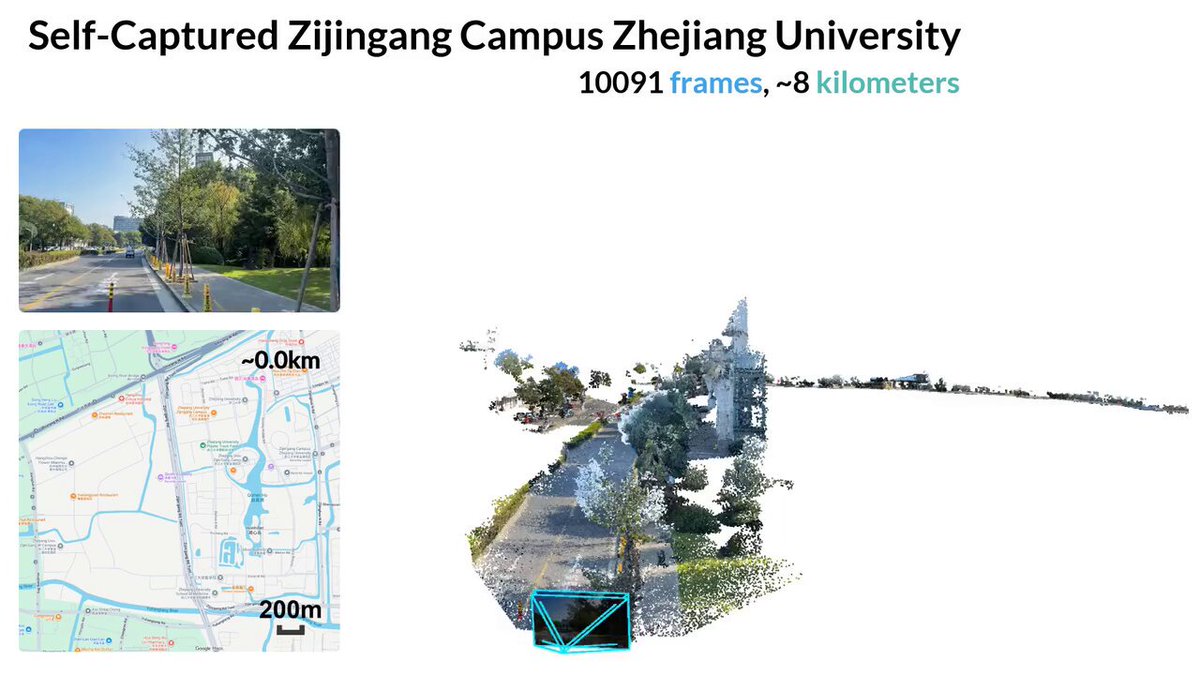
Spatial reconstruction is a long-context problem: real scenes come with hundreds of images. But O(N²) transformer-based models don’t scale efficiently. Introducing: 🤐ZipMap (CVPR ’26): Linear-Time, Stateful 3D Reconstruction via Test-Time Training (TTT). ZipMap “zips” a large image collection into an implicit TTT scene state in a single linear-time operation....

80,294 просмотров • 7 месяцев назад •via X (Twitter)

Комментарии: 29

Фото профиля Haian Jin
Haian Jin7 месяцев назад

🧵2/N Key to the speedup: we replace all global attention with TTT layers. Concretely, we first “zip” visual tokens into fast-weight MLPs by updating the weights with all tokens, then applying the updated MLPs back to the tokens. This update-then-apply mechanism plays a role analogous to vanilla bidirectional self-attention, while reducing the computational cost from O(N²) to O(N).

Фото профиля Haian Jin
Haian Jin7 месяцев назад

🧵3/N Fast speed without sacrificing quality: With careful designs of TTT, our model shows strong results across multiple benchmarks for both short and long sequence input, while being significantly faster. Left: Our runtime scales linearly; Given 750 images: <10s (ours) vs >200s (VGGT). Right: Our accuracy matches or surpasses quadratic-time SOTA (e.g., VGGT, π³).

Фото профиля Haian Jin
Haian Jin7 месяцев назад

🧵4/N Stateful reconstruction: the updated TTT fast weight can be viewed as an implicit scene state. In our paper, we demonstrate the benefits of having a stateful representation in real-time scene state querying and its extension to sequential streaming reconstruction.

Фото профиля Haian Jin
Haian Jin7 месяцев назад

For more results and technical details, please visit our project page: This work was done while I was a student researcher at @GoogleDeepMind. I’m very grateful for the inspiring research environment and the invaluable support from my collaborators @ChrisWu6080, @tianyuanzhang99, @RuiqiGao, @jon_barron, @Jimantha, and @holynski_.

Фото профиля ZotGuard
ZotGuard7 месяцев назад

VERY COOL!

Фото профиля Mayank Bhaskar
Mayank Bhaskar7 месяцев назад

Congratulations on the @CVPR 2026 acceptance! Would you or any of your co-authors like to present your papers in the @Cohere_Labs Computer Vision community? Cohere Labs Community Page: Here's the playlist to previous talks, if you are interested:

Фото профиля dailypapers.io
dailypapers.io7 месяцев назад

this is great work

Фото профиля Aryan Pandit ✈️ ECCV '26 🇸🇪
Aryan Pandit ✈️ ECCV '26 🇸🇪7 месяцев назад

Great work, seems really interesting!

Фото профиля Ang Cao
Ang Cao7 месяцев назад

Very cool work

Фото профиля Haian Jin
Haian Jin7 месяцев назад

Thank you, Ang!

Фото профиля ζ Pedram ζ
ζ Pedram ζ7 месяцев назад

Woah

Фото профиля Alexandre Devaux
Alexandre Devaux7 месяцев назад

Brilliant work! Looking forward to trying the code 🔥

Фото профиля 🎶
🎶7 месяцев назад

Cool

Фото профиля Yutang Lin
Yutang Lin7 месяцев назад

Great work, congrats!

Фото профиля Haian Jin
Haian Jin7 месяцев назад

Thank you, Yutang!

Фото профиля Wally
Wally7 месяцев назад

Very cool! Been exploring AI-generated impostor pipelines for real-time character rendering and the main pain point is view interpolation artifacts. This looks it could sidestep that entirely, looking forward to play around with the model!

Фото профиля 实践哥 Li
实践哥 Li7 месяцев назад

I love the zip idea

Фото профиля Brad Dangerfield
Brad Dangerfield7 месяцев назад

Sweet!

Фото профиля Utkarsh Mishra
Utkarsh Mishra7 месяцев назад

This is one of the most amazing things I've ever seen!

Фото профиля Sam Abdi
Sam Abdi7 месяцев назад

Seems really interesting and promising. Good work.

Фото профиля Haian Jin
Haian Jin7 месяцев назад

Thank you, Sam!

Фото профиля Daniel Sungho Jung
Daniel Sungho Jung7 месяцев назад

May i ask if there is any reason why robot and human motion were in main qualitative results? Any advantage of ZipMap in such scenarios?

Фото профиля Haian Jin
Haian Jin7 месяцев назад

Hi! We put them to just show how our methods work for dynamic scenes. We don’t mean to specifically emphasize it.

Фото профиля Daniel Sungho Jung
Daniel Sungho Jung7 месяцев назад

Thanks for the reply! I was curious as I am doing the tasks. Looking forward to visiting your poster at CVPR2026 :)

Фото профиля Nigel Higgs
Nigel Higgs7 месяцев назад

Hit me with an update when I can use the code

Фото профиля Haian Jin
Haian Jin7 месяцев назад

They will be released soon!

Фото профиля Nigel Higgs
Nigel Higgs7 месяцев назад

Awesome 👏🏽 just curious how well do you think this would work on video game footage?

Фото профиля Artem Sawistki
Artem Sawistki7 месяцев назад

That's dope! Can't wait to see the code

Фото профиля MistFaccoco
MistFaccoco7 месяцев назад

nice work!

Похожие видео

One-2-3-45: Any Single Image to 3D Mesh in 45 Seconds without Per-Shape Optimization paper page: Single image 3D reconstruction is an important but challenging task that requires extensive knowledge of our natural world. Many existing methods solve this problem by optimizing a neural radiance field under the guidance of 2D diffusion models but suffer from lengthy optimization time, 3D inconsistency results, and poor geometry. In this work, we propose a novel method that takes a single image of any object as input and generates a full 360-degree 3D textured mesh in a single feed-forward pass. Given a single image, we first use a view-conditioned 2D diffusion model, Zero123, to generate multi-view images for the input view, and then aim to lift them up to 3D space. Since traditional reconstruction methods struggle with inconsistent multi-view predictions, we build our 3D reconstruction module upon an SDF-based generalizable neural surface reconstruction method and propose several critical training strategies to enable the reconstruction of 360-degree meshes. Without costly optimizations, our method reconstructs 3D shapes in significantly less time than existing methods. Moreover, our method favors better geometry, generates more 3D consistent results, and adheres more closely to the input image. We evaluate our approach on both synthetic data and in-the-wild images and demonstrate its superiority in terms of both mesh quality and runtime. In addition, our approach can seamlessly support the text-to-3D task by integrating with off-the-shelf text-to-image diffusion models.

AK

179,061 просмотров • 3 лет назад

Check out our #ECCV2026 paper "Low-latency Event-based Object Detection with Spatially-Sparse Linear Attention", where we make linear attention sparse in space, recurrent in time, and parallel in training, enabling the first purely-linear-attention-based neural network for asynchronous object detection with #EventCameras, outperforming the previous best asynchronous method with 20x less computation with truly event-by-event inference on CPU! Code released! Paper: Code: Video: Event cameras promise extremely low-latency vision, but to fully exploit them, the neural network must be low-latency too. We introduce #SpatiallySparseLinearAttention (#SSLA) for asynchronous object detection directly from raw events. Linear attention is particularly appealing for event cameras: it can be trained efficiently in parallel on long event sequences, while at inference it operates recurrently, updating its prediction every time a new event arrives. The problem is that conventional linear attention updates its entire state for every event. For object detection, where fine spatial resolution matters, this quickly becomes expensive. Our key idea is simple: an event only carries information about a small spatial region, so why update the entire spatial state? SSLA updates only the relevant parts of the state, enabling fine-grained spatial representations while keeping per-event computation low. We achieve: - >20× lower per-event computation than the strongest prior asynchronous baseline - State-of-the-art accuracy among asynchronous object detection methods - Truly event-by-event inference on CPU, designed to preserve the latency advantage of event cameras Come to our poster on Friday September 11, 2026 from 4-6pm at ExHall #389 Reference: Haiqing Hao, Zhipeng Sui, Rong Zou, Zijia Dai, Nikola Zubić, Davide Scaramuzza, Wenhui Wang Low-latency Event-based Object Detection with Spatially-Sparse Linear Attention ECCV, 2026 Prophesee SynSense University of Zurich UZH Science European Research Council (ERC) UZHai UZH IfI Tesla BYD #EventCameras #ComputerVision #Robotics #DeepLearning #NeuromorphicVision #AI

Davide Scaramuzza

52,969 просмотров • 2 месяцев назад