Загрузка видео...
Не удалось загрузить видео
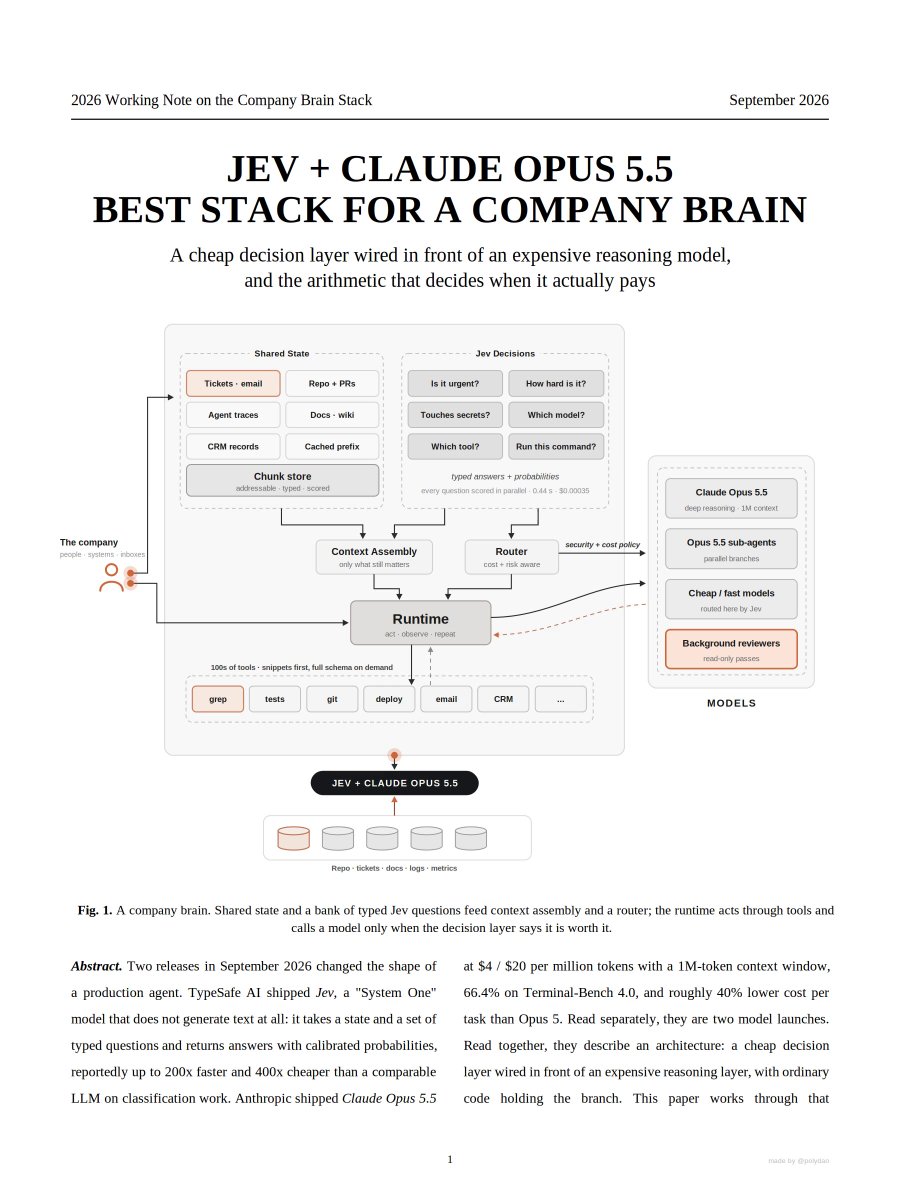
this harness stack is f*cking gold TypeSafe AI + LangChain finally dropped the layer that makes agents affordable at company scale: jev running inside the langchain agent loop as middleware the problem every big team hits: each fork in the loop is another full LLM call. at 10 agents... show more
31,666 просмотров • 5 дней назад •via X (Twitter)
Комментарии: 21

@N01ennn one thing I've noticed is the cost runaway when not controlling those loops tightly. Hit that wall building my own thing. Keeping an eye on loop depth saves sanity.

pure builder gold, trying this stack tonight broski

thx bro , im try , its was not hard make it because JEV cooking

LangChain's middleware finally exposes token burn per tool call. Still can't see which MCP server lied to your agent though.

fr good visualisation

The real unlock isn't another layer, it's killing redundant LLM calls before they happen.

Putting Jev inside the agent loop makes sense

Excellent. C'est le meilleur cas d'usage que j'ai pu constater jusqu'à maintenant. Merci

This actually solves the LLM cost problem for enterprise-scale agents, pretty neat.

Company-scale agent cost usually dies in the loop, not the model bill. I'd meter retries + tool calls per accepted artifact, and fail the run when the harness can't show that ratio.

Every fork billed as a full model call is how spend multiplies. Keep cheap decisions off that path, and hard-cap the loop either way.

this dashboard making my head hurt

crazy idea bros

middleware at the right layer serious cost control

This is like putting a fast tollbooth before the expensive road: cheap checks handle routine turns, while the frontier model takes the genuinely hard ones.

4 gates at 0.95 each = 0.81. enjoy

Absolute goldmine of a stack breakdown. Definitely testing this out!

This is realy focking gold

4 jev gates per step adds up fast

saving this stack bro

yeah counting the forks. that's where the cheap-model pick actually pays