正在加载视频...

视频加载失败

📢 Lyra: Generative 3D Scene Reconstruction via Video Diffusion Model Self-Distillation Got only one or a few images and wondering if recovering the 3D environment is a reconstruction or generation problem? Why not do it with a generative reconstruction model! We show that a camera-conditioned video diffusion model can...

66,934 次观看 • 1 年前 •via X (Twitter)

38 条评论

Sherwin Bahmani 的头像
Sherwin Bahmani1 年前

Previous work (left) trains image-to-3D models using real-world datasets with limited diversity. In contrast, we propose a self-distillation framework (right) for generative 3D scene reconstruction. Specifically, a pre-trained camera-controlled video diffusion model (GEN3C) with its RGB decoder output (teacher) supervises the rendering of the 3DGS decoder (student). Using a video model pre-trained on large-scale real-world 2D video data allows us to provide diverse and potentially infinite multi-view supervision.

Sherwin Bahmani 的头像
Sherwin Bahmani1 年前

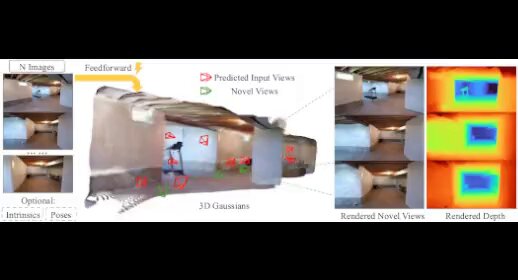
Our model generates 3DGS scenes from a single input image in a feed-forward manner generalizing across a wide range of scenarios., without the need for per-scene optimization.

Sherwin Bahmani 的头像
Sherwin Bahmani1 年前

Moreover, our framework easily extends to feed-forward 4D scene generation from a single input video.

Sherwin Bahmani 的头像
Sherwin Bahmani1 年前

Our approach seamlessly generalizes to full 3D scene generation from a single real image, without ever being trained on real-world data.

Sherwin Bahmani 的头像
Sherwin Bahmani1 年前

The generated 3D Gaussians can then be exported into into NVIDIA Isaac Sim based on 3DGUT to simulate humanoid robots in generated environments.

Sherwin Bahmani 的头像
Sherwin Bahmani1 年前

Joint work with @TianchangS @jiawei6_ren @huangjh_hjh Yifeng Jiang @Haithem_Turki @taiyasaki @davelindell @ZGojcic @FidlerSanja @HuanLing6 @JunGao33210520 @xuanchi13

Sherwin Bahmani 的头像
Sherwin Bahmani1 年前

@jiawei6_ren @huangjh_hjh @Haithem_Turki @taiyasaki @DaveLindell @ZGojcic @FidlerSanja @HuanLing6 @JunGao33210520 @xuanchi13 Check out this very related work Bolt3D ( at ICCV next month by @StanSzymanowicz @jasonyzhang2 @_pratul_ @RuiqiGao @ArthurBrussee @holynski_ @rmbrualla @jon_barron @philipphenzler

Sherwin Bahmani 的头像
Sherwin Bahmani1 年前

@jiawei6_ren @huangjh_hjh @Haithem_Turki @taiyasaki @DaveLindell @ZGojcic @FidlerSanja @HuanLing6 @JunGao33210520 @xuanchi13 @StanSzymanowicz @jasonyzhang2 @_pratul_ @RuiqiGao @holynski_ @rmbrualla @jon_barron @philipphenzler Special thanks to @robrombach @andi_blatt and the rest of the team at @bfl_ml for open-sourcing FLUX ( We use FLUX to generate high-quality input images and lift them into 3D.

Matthias Niessner 的头像
Matthias Niessner1 年前

Amazing work!

Sherwin Bahmani 的头像
Sherwin Bahmani1 年前

Thanks Matthias 🍻

Kai He 的头像
Kai He1 年前

Strong 👍👍🥳

Sherwin Bahmani 的头像
Sherwin Bahmani1 年前

Not as strong as you 😌

Eduard Zamfir 的头像
Eduard Zamfir1 年前

Uff 😮‍💨 sky is the limit! 🚀

Sherwin Bahmani 的头像
Sherwin Bahmani1 年前

Danke du Spruecheklopfer 🤪

Oliver Hahn 的头像
Oliver Hahn1 年前

Machine! Congrats 🚀

Sherwin Bahmani 的头像
Sherwin Bahmani1 年前

Danke Bro 😎

Lily Goli 的头像
Lily Goli1 年前

looks amazing!! 🎉

Sherwin Bahmani 的头像
Sherwin Bahmani1 年前

Thanks Lily 😊

Stephen J. Caggiano 的头像
Stephen J. Caggiano1 年前

🔥❤️👏🏼

Ziya Erkoç 的头像
Ziya Erkoç1 年前

Congrats, Sherwin!🎉🎉

Sherwin Bahmani 的头像
Sherwin Bahmani1 年前

Thanks Ziya 🫡

Tuan Ngo 的头像
Tuan Ngo1 年前

Amazing!!! Congrats Sherwin

Sherwin Bahmani 的头像
Sherwin Bahmani1 年前

Thanks big guy 🙏

Ison Ward 的头像
Ison Ward1 年前

Cool!That looks like a good time

Sai Tedla 的头像
Sai Tedla1 年前

This is insane.

Phil Franco 的头像
Phil Franco1 年前

that looks cool!

Yuyang Zhao 的头像
Yuyang Zhao1 年前

Amazing work! Congrats, Sherwin!

Sherwin Bahmani 的头像
Sherwin Bahmani1 年前

Thanks Yuyang 🤪

Hadi Alzayer 的头像
Hadi Alzayer1 年前

Very cool work! Congrats on the release

Sherwin Bahmani 的头像
Sherwin Bahmani1 年前

Thanks Hadi 😊

:3 的头像
:31 年前

This is over 20 years ago:

Felix Taubner 的头像
Felix Taubner1 年前

The 4D 🐐 🤩

Sherwin Bahmani 的头像
Sherwin Bahmani1 年前

No, you are the 4D 🐐😮‍💨

Mohamad Shahbazi 的头像
Mohamad Shahbazi1 年前

Really cool work and amazing results Sherwin! :) Was wondering, how sensitive the 3DGS decoder is to the multivew inconsistencies?

Sherwin Bahmani 的头像
Sherwin Bahmani1 年前

Thanks! We learn to smoothen inconsistencies with LPIPS loss. Obviously, a more consistent diffusion model will make it easier to get consistent output. The current viewpoint change is mainly limited because the diffusion output gets more and more inconsistent far away from the input view. Hope to improve that!

Ethan Weber 的头像
Ethan Weber1 年前

Congrats! I really like the ideas here. 🙂

Sherwin Bahmani 的头像
Sherwin Bahmani1 年前

Thanks Ethan 😊

Andrew Guo 的头像
Andrew Guo7 个月前

wow! this is cool

相关视频

DreamCraft3D: Hierarchical 3D Generation with Bootstrapped Diffusion Prior paper page: present DreamCraft3D, a hierarchical 3D content generation method that produces high-fidelity and coherent 3D objects. We tackle the problem by leveraging a 2D reference image to guide the stages of geometry sculpting and texture boosting. A central focus of this work is to address the consistency issue that existing works encounter. To sculpt geometries that render coherently, we perform score distillation sampling via a view-dependent diffusion model. This 3D prior, alongside several training strategies, prioritizes the geometry consistency but compromises the texture fidelity. We further propose Bootstrapped Score Distillation to specifically boost the texture. We train a personalized diffusion model, Dreambooth, on the augmented renderings of the scene, imbuing it with 3D knowledge of the scene being optimized. The score distillation from this 3D-aware diffusion prior provides view-consistent guidance for the scene. Notably, through an alternating optimization of the diffusion prior and 3D scene representation, we achieve mutually reinforcing improvements: the optimized 3D scene aids in training the scene-specific diffusion model, which offers increasingly view-consistent guidance for 3D optimization. The optimization is thus bootstrapped and leads to substantial texture boosting. With tailored 3D priors throughout the hierarchical generation, DreamCraft3D generates coherent 3D objects with photorealistic renderings, advancing the state-of-the-art in 3D content generation.

AK

161,530 次观看 • 3 年前

One-2-3-45: Any Single Image to 3D Mesh in 45 Seconds without Per-Shape Optimization paper page: Single image 3D reconstruction is an important but challenging task that requires extensive knowledge of our natural world. Many existing methods solve this problem by optimizing a neural radiance field under the guidance of 2D diffusion models but suffer from lengthy optimization time, 3D inconsistency results, and poor geometry. In this work, we propose a novel method that takes a single image of any object as input and generates a full 360-degree 3D textured mesh in a single feed-forward pass. Given a single image, we first use a view-conditioned 2D diffusion model, Zero123, to generate multi-view images for the input view, and then aim to lift them up to 3D space. Since traditional reconstruction methods struggle with inconsistent multi-view predictions, we build our 3D reconstruction module upon an SDF-based generalizable neural surface reconstruction method and propose several critical training strategies to enable the reconstruction of 360-degree meshes. Without costly optimizations, our method reconstructs 3D shapes in significantly less time than existing methods. Moreover, our method favors better geometry, generates more 3D consistent results, and adheres more closely to the input image. We evaluate our approach on both synthetic data and in-the-wild images and demonstrate its superiority in terms of both mesh quality and runtime. In addition, our approach can seamlessly support the text-to-3D task by integrating with off-the-shelf text-to-image diffusion models.

AK

179,061 次观看 • 3 年前

📢📢 𝐀𝐯𝐚𝐭𝟑𝐫 📢📢 Avat3r creates high-quality 3D head avatars from just a few input images in a single forward pass with a new dynamic 3DGS reconstruction model. Video: Project: Our core idea is to make Gaussian Reconstruction Models animatable. We find that a simple cross-attention to an expression code sequence is already sufficient to model complex facial expressions. We then incorporate position maps from DUSt3R and feature maps from Sapiens to facilitate the prediction task. While DUSt3R's position maps act as a pixel-aligned initialization for the Gaussians' positions, the Sapiens feature maps help the cross-view transformer to match corresponding image tokens in the 4 input images. One major challenge in creating a 3D head avatar from smartphone images comes from inconsistent facial expressions when the subject could not remain perfectly static during the capture. We eliminate this static requirement by simply showing our model input images with different facial expressions during training. This technique makes our model robust to inconsistent input images later on. Finally, we show that despite the model has been trained with 4 input images, one can even create a 3D head avatar when only a single image is available. To achieve this, we employ a pre-trained 3D GAN to lift the single image to 3D and then render the 4 input images for our model. This allows us to create 3D head avatars from single images and even highly out-of-distribution examples like AI generated faces, paintings or statues. Great work by Tobias Kirschstein from his internship at Meta with Javier Romero, Artem Sevastopolsky, and Shunsuke Saito

Matthias Niessner

74,863 次观看 • 1 年前