Video wird geladen...
Video konnte nicht geladen werden
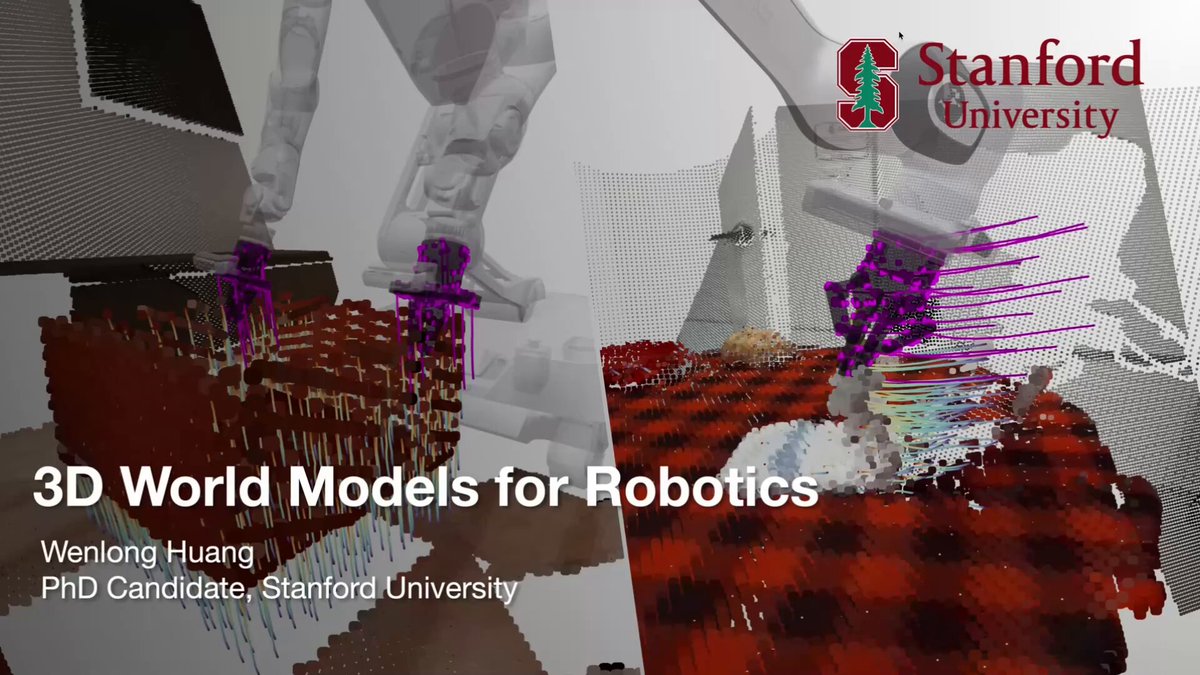
Policies trained on real robot data via imitation can be surprisingly capable. But for domains like dexterous manipulation, they are often not quite good enough: they move slowly, miss grasps, make unreliable contact, and fail under small perturbations. Can we improve them without any additional data collection on the... show more
35,328 Aufrufe • vor 3 Monaten •via X (Twitter)
13 Kommentare

The most direct recipe in “real-to-sim-to-real” policy improvement is to take a real-world policy, put it in simulation, and run RL to improve it cheaply. But this often fails in contact-rich manipulation because unconstrained RL exploits discrepancies between simulation and reality. Since simulators imperfectly model contact, friction, compliance, geometry, and force, RL finds simulated solutions that underperform on real hardware. (2/10)
A standard fix is to keep the learned policy close to the real-world policy, using a “distributional” constraint (like KL). But this often creates a difficult tradeoff: Too loose → the policy exploits simulation. Too tight → the policy barely improves. So we asked: is there a better way to constrain sim RL that allows policies to actually improve, while avoiding exploitation behavior? (3/10)
To realize this, SCORE constrains RL improvement in simulation to the real-world policy’s support: the actions the real-world policy can plausibly generate with non-zero likelihood. We realize a support constraint by only learning to steer in simulation, building on our prior work on diffusion steering. Freezing the base generative control policy (flow/diffusion policy) trained on real robot data, we use RL to learn how to steer the policy, i.e determine which latent inputs lead to success, rather than finetuning the policy itself. This lets simulation select among real-world behaviors, rather than inventing actions that may be unsafe or untransferable. In this case diffusion steering is not just a convenient choice of RL algorithm, but actually necessary to enforce support constraints. (4/10)
SCORE gets the benefits of simulation for policy improvement: parallel interaction, privileged state, resets, and robustness to perturbations. Meanwhile, it avoids much of the manual engineering usually needed to make sim RL work, such as dense reward shaping, curriculum learning, or policy distillation. You don’t need to finetune the base policy, just directly transfer the steering policy from sim-to-real. (5/10)
This makes the iteration loop really fast! We can go from task setup to real-world deployment for a new task in just half a day, turning a brittle base policy into one that is much more successful, while being robust, faster and more precise. For instance, we can see the ability to robust, continuous block picking with much higher throughput than possible before. (6/10)
The empirical results are quite striking. While only using simulated steering, we see a 2.4x improvement in real-world success rate, and a 36.8% improvement in policy throughput. We also see the policy demonstrating retry and robustness behaviors that the base-policy failed to show. Interestingly, the relatively coarse knob of policy steering is able to solve some pretty cool, high-dexterity problems. (7/10)
What is pretty cool is that SCORE does not require perfect (or even near-perfect) base policies for successful improvement. What matters is coverage of the base-policy: failures, recoveries, and play data can all expand what the real-world policy is able to do. Even if the base policy does not use these behaviors reliably for zero-shot success, SCORE can learn to steer towards them in simulation. Some of our most robust policies came not from cleaner datasets, but from broader ones! (8/10)
Now, SCORE is not magic - there are clear limitations. Real-world policy can be improved by choosing better behaviors inside its support, but it cannot create behaviors that were never present in the data, making it reliant on a level of base policy coverage and capabilities. (9/10)
This project worked surprisingly well, and was a huge amount of hard work by @yu_raymond5 and @willhuey9. No matter what task I threw at them, they got it to work - really incredible work! And it really works surprisingly well, we highly recommend you try it out. This was joint work with @mukadammh and Anusha Nagabandi at Amazon! Website (lots of fun videos!): Paper: (10/10)
I also want to shout out some related work from friends over at RAI - ExpertGen ( that investigates related ideas! :)
Oh also, @yu_raymond5 is applying for PhD programs this Fall! Prospective advisors - he is awesome, hire him :)

Interesting work! Sounds like the findings have some overlap with our recent work, where we ask how much human demonstration data is needed when training agents on 60 years of self-play experience in sim.

This is a smart use of simulation.