Загрузка видео...

Не удалось загрузить видео

На главную

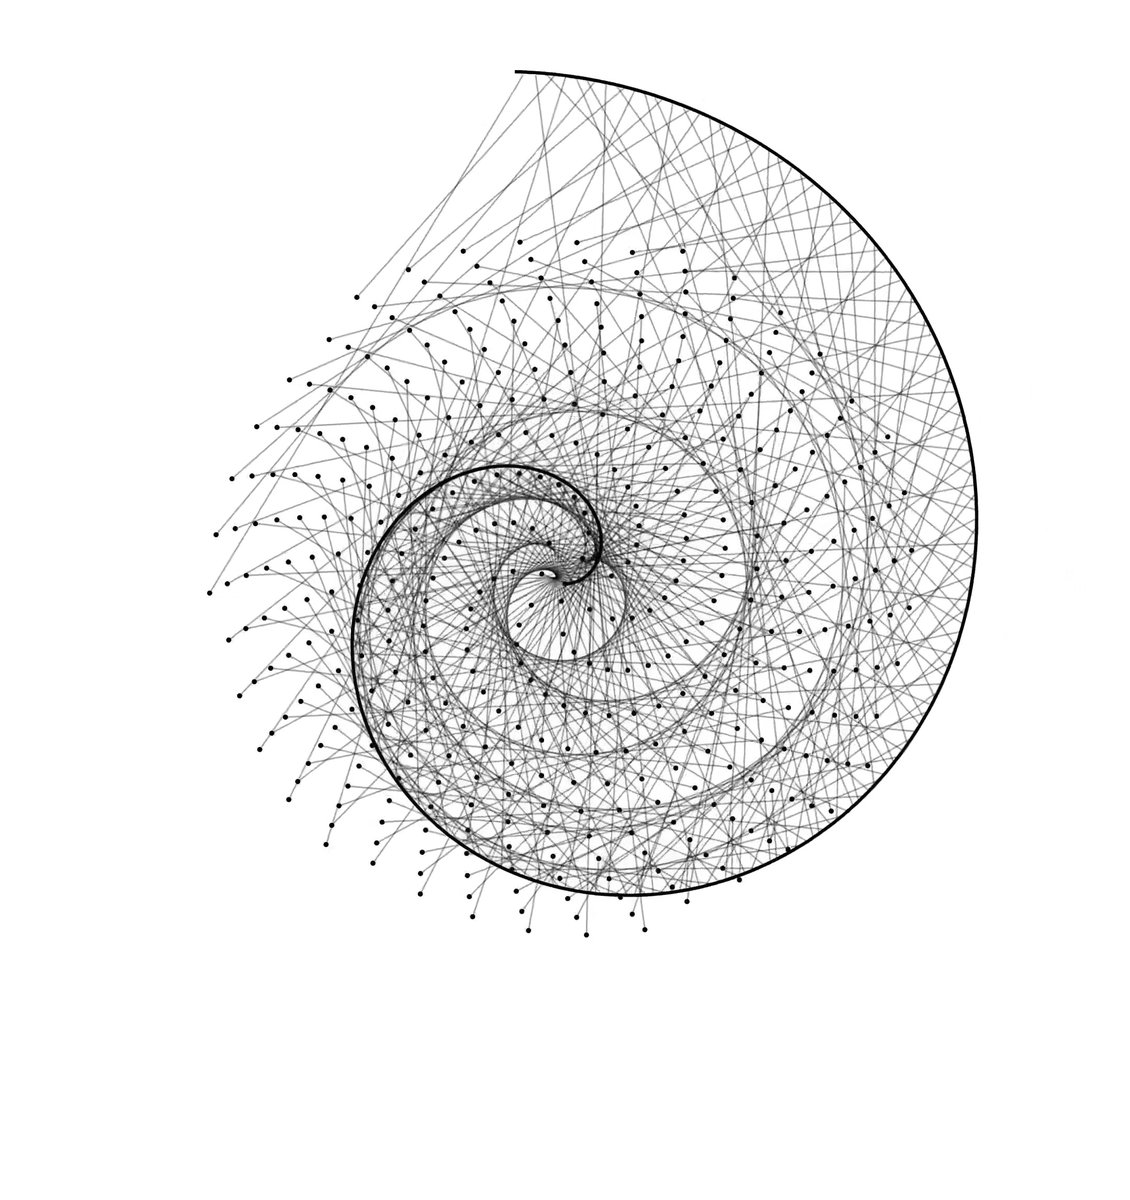
We often hear that Machine Learning models learn patterns in data. But what does that look like in geometry? Picture dropping an elastic mesh into a cloud of points and letting it adapt. How would it bend, stretch, and settle so it matches the shape hiding in the data?...

23,021 просмотров • 9 месяцев назад •via X (Twitter)

Комментарии: 0

Нет доступных комментариев

Здесь появятся комментарии из оригинального поста

Похожие видео

The Machine That Learns The Law Behind The Data A very very interesting US Patent US10963540B2 - Physics Informed Learning Machine describes a learning system that does not begin with data alone. It begins with a physical model, usually written as a differential equation (or PDE) dx/dt = f(x,t) A normal Machine Learning model sees scattered data and tries to fit it. A physics-informed learning machine starts with a law. Then it treats the data as evidence that updates what the model believes about the physical system. For this application, I use the patent idea on NASA C-MAPSS Turbofan engine data. The machine watches multivariate telemetry from a degrading engine and infers a hidden health state that is not measured directly. From that posterior belief, it estimates the engine’s remaining useful life. In the main 3D scene, the engine lifetime is turned into a tunnel. The spiral ribbons are real sensor channels evolving over cycle-time. The glowing core is the inferred health state. The surrounding cloud is uncertainty. The orange wall ahead is the predicted failure horizon. So the big picture is: sensor evidence comes in, posterior belief tightens, and the machine moves from uncertainty toward a concrete failure prediction. The inset posteriors make that explicit. The health posterior shows where the model believes the hidden engine condition sits at the current moment, and how sharply it believes it. The RUL posterior shows the same idea for remaining life... early on it is broad, later it shifts left and narrows as the machine becomes more certain about how close failure is. This idea is not limited to engines. The same idea can apply to data centers, CPUs, GPUs, cooling systems, power grids, robotics, batteries, and any machine that produces telemetry while obeying physical constraints. In an age where machine learning runs on massive hardware infrastructure, this kind of model matters: it can turn noisy sensor streams into early warnings before expensive systems fail.

Mathelirium

17,843 просмотров • 5 месяцев назад

Former Meta Chief AI Scientist Yann LeCun on the three paradigms of machine learning — and why the third is what made ChatGPT possible: Here's each one, and where it breaks. First, supervised learning. You tell the machine the answer. "You show it a picture, let's say of a table, and you tell it this is a table. So it's supervised because you tell it what the correct answer is." Get it wrong, and the machine rewrites itself: "The system computes its output, and if it says something else than table, then it's going to adjust its parameters, its internal structure, so that the output it produces gets closer to the output you want." Repeat at scale and something more than memorisation appears: "Eventually the system will find a way to recognize every image you trained it on, but also images it's never seen that are similar to the one you train it on. This is called a generalization ability." The limit: a human has to supply every single answer. That doesn't scale to the size of the internet. Second, reinforcement learning. You don't give the answer, only a verdict. "You don't tell the system what the correct answer is. You only tell it whether the answer it produced was good or bad." Learning to ride a bike, essentially: "You try to ride a bike and you don't know how to ride the bike and after a while you fall. So you know you did something bad and so you change your strategy a little bit. And eventually you learn how to ride a bike." For years the field assumed this was the closest thing to how animals actually learn. Yann LeCun's verdict: "Now it turns out reinforcement learning is extremely inefficient." It dominates wherever failure is free: "It works really well if you want to train a system to play chess or play go or poker, because you can have the system play millions and millions of games against itself and basically fine-tune itself. But it doesn't really work in the real world." The limit, in one image: "If you want to train a car to drive itself, you're not going to do it with reinforcement learning. It's going to crash thousands of times." On robotics he's careful rather than dismissive: "Reinforcement learning can be part of the solution, but it's not the complete answer. It's not sufficient." Third, self-supervised learning. You tell the machine nothing at all. "And this is what has enabled the recent progress in natural language understanding and chatbots." The strange part is that you stop asking for a task: "You don't train the system to accomplish any particular task. You just train it to basically capture the structure..." The method is deliberate sabotage: "You take a piece of text, you corrupt it in some way, by for example removing some words, and then you train a big neural net to predict the words that are missing." And one narrow version of that trick runs every chatbot on Earth: "A special case of this is that you take a piece of text and the last word in that text is not visible, and so you train the system to predict the last word in that text — and this is the way large language models are trained on." So why did the third one win? Supervised learning needs a human. Reinforcement learning needs a crash. Self-supervised learning needs neither — because the missing word and the correct answer are the same thing. The data grades itself.

Big Brain AI

49,293 просмотров • 2 месяцев назад

New PNAS paper. Historical GDP per capita data is scarce, but data on the places of birth, death, and occupations of famous individuals is abundant. In this paper we estimate the historical GDP per capita of hundreds of regions in Europe and North America using a machine learning model that leveraged data on about 500k famous biographies. Our estimates more-or-less quadruple the availability of historical GDP per capita estimates for the last 700 years. So why use biographies to augment historical GDP per capita data? Biographical data contains information about people who might have contributed directly to economic growth, like James Watt, or that were attracted to wealthy places looking for patrons, like Michelangelo. So we--mainly Philipp (Philipp Koch)--used this data to construct hundreds of features describing each European region. Then, we trained a machine learning model to find the features that explained most of the variance in a cross-validation test, where we split regions multiple times into a training set and a test set. On average, the model explained about 90% of the variance in GDP per capita of the regions it had not seen during training. But we wanted to go further, and Philipp really went to town by looking at different ways to validate our estimates. We found our estimates correlate positively with historical measures of wellbeing, church building activity, urbanization, and body height. We also used these measures to reproduce the basic Atlantic trade result of Acemoglu, Johnson, and Robison and to explore the economic consequences of the famous Lisbon earthquake of 1755. But what I personally loved most about this project, other than working with Philipp Koch and V, is that it shows that we can use machine learning methods not only to explore the future, but the past. There is a bright and growing future in the use of machine learning for economic history. Hope you enjoy the paper and the data. You can find links to the paper and a data exploration tool in the first comment.

César A. Hidalgo

54,365 просмотров • 2 лет назад

I don’t know if we live in a Matrix, but I know for sure that robots will spend most of their lives in simulation. Let machines train machines. I’m excited to introduce DexMimicGen, a massive-scale synthetic data generator that enables a humanoid robot to learn complex skills from only a handful of human demonstrations. Yes, as few as 5! DexMimicGen addresses the biggest pain point in robotics: where do we get data? Unlike with LLMs, where vast amounts of texts are readily available, you cannot simply download motor control signals from the internet. So researchers teleoperate the robots to collect motion data via XR headsets. They have to repeat the same skill over and over and over again, because neural nets are data hungry. This is a very slow and uncomfortable process. At NVIDIA, we believe the majority of high-quality tokens for robot foundation models will come from simulation. What DexMimicGen does is to trade GPU compute time for human time. It takes one motion trajectory from human, and multiplies into 1000s of new trajectories. A robot brain trained on this augmented dataset will generalize far better in the real world. Think of DexMimicGen as a learning signal amplifier. It maps a small dataset to a large (de facto infinite) dataset, using physics simulation in the loop. In this way, we free humans from babysitting the bots all day. The future of robot data is generative. The future of the entire robot learning pipeline will also be generative. 🧵

Jim Fan

165,488 просмотров • 2 лет назад