Video yükleniyor...

Video Yüklenemedi

Ana Sayfaya Dön

Martin Keen from IBM just explained the one thing separating "chatbot users" from $300K AI architects > most people use Claude Opus 4.8 as a temporary tool -> the pros build it a permanent memory it's called the CoALA framework. the 4 layers your agent actually needs: > Working...

10,442 görüntüleme • 4 ay önce •via X (Twitter)

0 Yorum

Yorum bulunmuyor

Orijinal gönderinin yorumları burada görünecek

Benzer Videolar

HERMES AGENT LEARNS FROM ITS OWN MISTAKES. UPDATES ITS MEMORY. CREATES ITS OWN SKILLS. NO CLOUD. EVERYTHING STORED LOCALLY. THIS IS HOW THE SELF-IMPROVING LOOP WORKS. most agents start from zero every session. Hermes carries forward what it learned. THREE MEMORY SYSTEMS: 1. PROCEDURAL MEMORY (how to act) stored in ~/.hermes/skills/ as SKILL.md files. when the agent repeats a complex workflow, it saves the procedure as a reusable skill. next time the same task comes up, it follows the skill instead of figuring it out again. you can also create skills explicitly: "create a skill called video-prep that captures how I format my video scripts. spoken english, define jargon inline, no em-dashes, close with a catchphrase." the agent writes the SKILL.md. available as a slash command from that moment. Hermes ships with 90+ skills. the number grows the longer you use it. 2. SEMANTIC MEMORY (durable facts about you) stored in ~/.hermes/memory/memory.md the agent scans conversations for facts worth remembering. preferences, habits, corrections, project details. real example from the video: agent tried to scrape a YouTube channel. URL was wrong. it failed. it updated memory.md with the correct URL pattern so it never makes the same mistake again. you can also save explicitly: "save to memory that my favorite testing framework is pytest" the agent updates memory.md immediately. this file loads into context on every session. the agent knows you better every week. 3. EPISODIC MEMORY (chat history) stored in ~/.hermes/state.db (local SQLite). every conversation. every tool call. every result. searchable with FTS5 full-text search. "search our past sessions. what was the first thing I ever said to you?" the agent queries state.db and finds it. over time, auxiliary models consolidate episodic memory into semantic memory. distilling recurring patterns into durable facts. THE SELF-IMPROVING LOOP: every agent run follows this cycle: → you send a prompt → working memory loads: SOUL.md + memory.md + relevant skills + chat history → agent calls tools (terminal, browser, delegate_task) → agent completes the task, replies to you → AFTER the reply: agent checks "did I learn something worth saving?" → if yes: updates memory.md or creates a new skill → next session starts smarter than the last this happens automatically. you don't ask the agent to learn. it decides what to remember on its own. WHAT MAKES THIS DIFFERENT FROM CLAUDE CODE: Claude Code has memory too. but Hermes stores everything locally. no cloud. your data never leaves your machine. Claude Code doesn't auto-create skills from experience. Hermes turns repeated workflows into reusable procedures. Claude Code memory is instruction-based. Hermes memory is conversational and self-updating. over months of usage, Hermes builds a knowledge base of your preferences, your projects, your mistakes, and the procedures that work for your specific workflow. the agent that remembers your birthday also remembers why your last deploy failed. NO EMBEDDINGS. PLAIN TEXT. Hermes does not use embeddings or RAG for memory. skill and memory search runs on plain text keyword matching. simpler. faster. no vector database to maintain. works entirely offline on your local machine. DELEGATE TO CLAUDE CODE: Hermes can spawn a sub-agent that runs Claude Code in headless mode: "spawn a sub-agent using Claude CLI to build a Python script that fetches the top 5 Hacker News stories to markdown." Hermes delegates. Claude Code writes the code. result returns to Hermes. Hermes runs the script and delivers the output. use Hermes for orchestration. use Claude Code for heavy coding. both tools. not competitors. WHAT HERMES DOES NOT HAVE: no built-in eval or LMOps system. no LangSmith, no LangFuse integration out of the box. trajectory export and logs exist but there is no automated quality tracking. if you need eval, build it yourself or connect external tools. the loop is self-improving. measuring how well it improves is on you. comment LOOP and I'll send you the configs that control how fast Hermes learns and what it remembers. memory limits, skill auto-creation triggers, and the auxiliary model that runs the learning. Replace your entire team with 8 hermes agents👇

YanXbt

23,088 görüntüleme • 3 ay önce

New short course: Long-Term Agentic Memory with LangGraph. Learn to build an agent with long-term memory in this course developed in collaboration with taught by its Co-Founder and CEO, Harrison Chase! Personal assistance and productivity tasks have become important use cases for agents. An important feature of an AI assistant, such as a coding or calendar assistant, is its ability to keep improving over time from its experience. Agent memory is the key capability that enables this. To add memory to an agent, you must first figure out what to store and what to retrieve when it is time to use the information. Additionally, you’ll have to decide when to update the stored information. For example, you might update in each iteration loop of the agent or perform updates in the background, with a helper agent. In this course, you will learn a mental framework to build agents with long-term memory. You'll create a useful email assistant that can respond, ignore, and notify using writing, scheduling, and memory-management tools. You’ll develop your agent's memory by adding facts to its memory store, provide examples to learn the user's preferences, and optimize system prompts to evolve instructions based on previous responses. In detail, you’ll: - Learn how the three types of memory--semantic, episodic, and procedural–and the two update mechanisms–via hot path and in the background–apply to your agents. - Build an email agent with writing, scheduling, and availability tools, along with a router that triages incoming email and handles it accordingly by ignoring, responding, or notifying the user. - Add tools to your email agent that allow it to operate on semantic memory by learning facts about the user, storing them in a long-term memory store, and searching over them in future interactions. - Incorporate episodic memory, in the form of few-shot examples, in the triage step of your agents to help them learn and update user preferences. - Add procedural memory as system prompts, optimized with feedback to improve the instructions the agent follows. Learn how to approach memory in agents, and start building agents with long-term memory with LangGraph! Please sign up here:

Andrew Ng

132,058 görüntüleme • 1 yıl önce

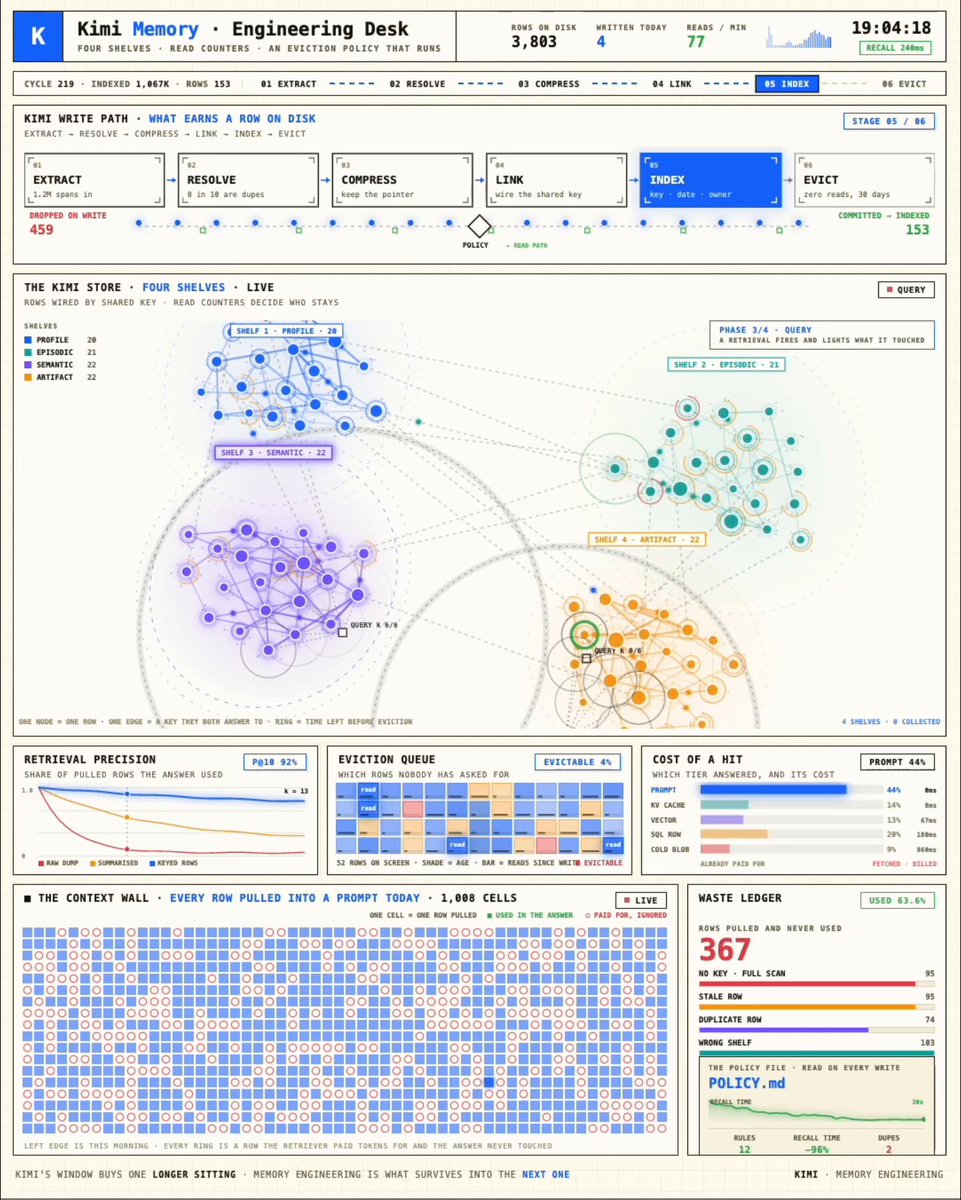
Engineer runs a Kimi K3 memory layer that costs $11 a month and remembers what a $500,000 vector database keeps losing. No embeddings. Four nodes and one rule about what's allowed to be forgotten. He published the whole schema. His version starts from the opposite idea. Memory is not a pile you search. It's a set of claims that expire unless something keeps paying to keep them. Four nodes. Every memory carries a clock someone has to reset: > WRITER - stores a fact with the reason it mattered, never raw text > DECAY - ages every memory down. Silence is deletion > RENEWER - only re-lifts a memory the model actually used again > GRAVE - holds what died, and why nobody reached for it Three nodes keep memory alive. One keeps the dead ones. Recall isn't storage here. It's rent a fact has to keep earning. That's the entire design. When everything is remembered forever, the useful and the stale retrieve identically. He replayed two months of agent context. 90,000 stored facts. 71,000 never retrieved once. The vector store returned all of them on similarity. Similarity graded closeness. Nobody graded whether the memory was ever right. Everyone else stuffs more into the context window and calls it memory. He built a layer that lets a fact die unless it keeps proving itself. The cost isn't storage. It's finding out how much of what your agent "knows" it has never once used. The article below is the full build - node prompts, the decay curve, the renewal rule. Save it. You'll want it open in the other tab.

wast3

67,778 görüntüleme • 1 ay önce

THIS GUY BUILT AN AUTONOMOUS AI AGENT OUT OF CLAUDE CODE + OBSIDIAN and this is way more interesting than another “use AI to take notes” demo the trick is simple: Obsidian is not the writing app here. it becomes the agent’s memory, task board, and context folder. Claude Code is not just answering prompts. it reads the vault, edits files, follows instructions, and keeps moving through the work like a junior operator with a filesystem. the reusable setup looks like this: 1. create an Obsidian vault for one project 2. keep goals, rules, tasks, decisions, and references as markdown files 3. point Claude Code at the folder 4. give it a clear operating loop: read context → choose next task → execute → write back what changed 5. use the notes as persistent memory instead of re-explaining the project every chat that’s the part people miss. the “agent” is not magic. it’s the boring combination of: - local files - explicit rules - task state - write access - a model that can run through the repo/vault Obsidian makes the memory human-readable. Claude Code makes the memory executable. that combo is why the video worked: it turns a notes app into an operating surface for actual work. best use cases: - content systems - research vaults - coding projects - client ops docs - personal knowledge bases that need actions, not just storage the caveat: if your vault is messy, your agent becomes messy too. folders, naming, “done” criteria, and forbidden actions matter more than the prompt. but once the structure is clean, this is one of the easiest ways to build an agent that remembers what happened yesterday without paying for a full custom app.

kocer

30,403 görüntüleme • 3 ay önce

THIS GUY CONNECTED HIS AI AGENTS TO HIS OBSIDIAN AND BUILT A BRAIN THAT LEARNS ON ITS OWN. HERE'S HOW TO BUILD IT Obsidian is just markdown files sitting in a folder. That turns out to be the perfect memory for an AI agent, because an agent can read and write those files directly. He wired his agents into the vault so they pull context from it, do the work, and write what they learned back. The notes aren't the point. The loop is, and it gets sharper every cycle How to build it: 1. Point an agent at your vault. The fastest way, no plugins, no API keys: open a terminal and run npx obsidian-mcp /path/to/your/vault. That exposes your Obsidian folder to Claude as a tool it can read, search, and write to. Add it to your Claude Code or Cowork config and restart 2. Confirm it can see the brain. Ask it: "list the notes in my vault and summarize what's in them." If it reads them back, the connection is live. Now it starts every task with everything the vault already holds instead of from zero 3. Give each agent one job and a write-back rule. Tell it: "research this, then save what you found as a new note in /brain with links to related notes." One agent researches, one summarizes, one plans. Each writes its output back into the vault 4. Close the loop. Add one line to every agent's instructions: "read /brain before starting, write your result back when done." Now each task leaves the vault richer, and the next run reads that before it works. It compounds instead of resetting 5. You only steer. Review what the brain produces, point it at the next thing. The agents handle the reading, writing, and connecting The edge isn't better notes. It's a brain that feeds itself, so the work gets sharper every cycle instead of starting over Bookmark this

Yarchi

58,643 görüntüleme • 4 ay önce